

What is Data Movement?
Data movement is the process of transferring data from one place to another. This process is typically initiated when there are system upgrades, consolidations, or when there is a need to synchronize data across different platforms for business intelligence or other operational purposes.
Data movement ensures that the right data is available at the right place and at the right time. The key, however, is to transfer data seamlessly without impacting system performance, allowing businesses to continue their operations smoothly while the data is being moved.
As IBM puts it, "moving data from point A to point B is straightforward. What makes data movement complex is scale." That complexity comes from moving many sources, at high volumes, on tight schedules, without breaking the systems that depend on the data.
How Does Data Movement Work?
Every data movement process follows the same basic path, whatever the method:
Identify the source and target. Decide which systems the data comes from (databases, applications, files, APIs) and where it needs to go (a data warehouse, a data lake, a cloud platform, or another application).
Extract the data. Read either the full dataset or only the records that changed since the last run.
Transform it, if needed. Clean, reformat, or restructure the data to match the target. Depending on the method, this happens before loading (ETL) or after (ELT).
Load it into the target. Write the data into the destination tables, files, or applications.
Validate and monitor. Compare record counts and totals between source and target, and set alerts for failed or delayed runs.
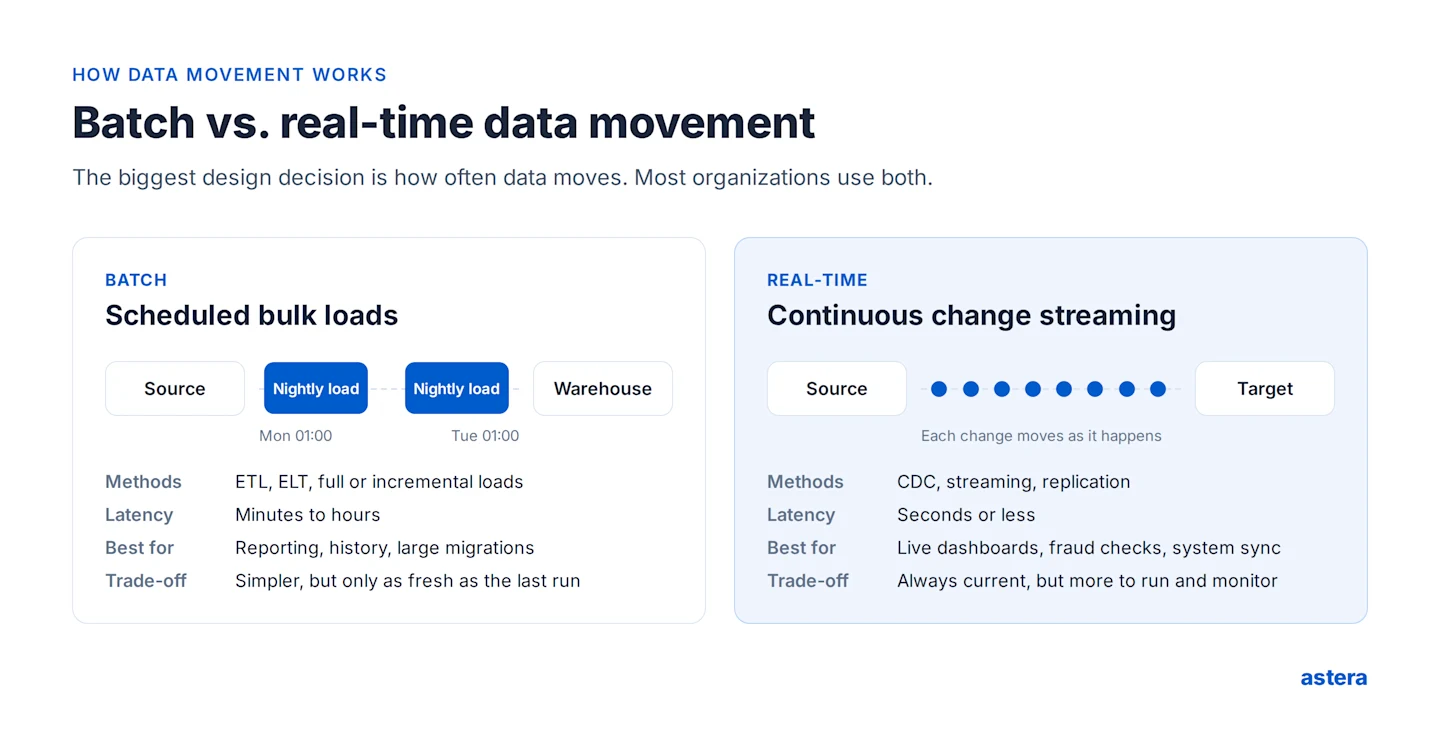
Batch vs. real-time data movement
The biggest design decision is how often data moves.
Batch data movement | Real-time data movement | |
How it works | Moves data in scheduled bulk loads (hourly, nightly, weekly) | Moves each change continuously as it happens |
Typical methods | ETL, ELT, full or incremental loads | CDC, streaming, replication |
Latency | Minutes to hours | Seconds or less |
Best for | Reporting, historical analysis, large migrations | Fraud detection, live dashboards, operational sync between systems |
Trade-off | Simpler and cheaper, but data is only as fresh as the last run | Always current, but more complex to run and monitor |
Types of Data Movement
Data movement can be categorized into several types based on the purpose and specific requirements of the data transfer. Common methods include Extract, Transform, and Load (ETL), Extract, Load, and Transform (ELT), data replication, and Change Data Capture (CDC). Each of these methods serves a unique purpose and is chosen based on factors such as the volume of data, the complexity of the data structures, and the need for real-time data availability.
Method | What it does | Typical timing | Best for |
ETL | Transforms data before loading it | Batch | Structured reporting, strict data standards |
ELT | Loads raw data, then transforms it in the target | Batch | Large volumes in cloud data warehouses |
Data replication | Keeps exact copies of data in several places | Real-time or scheduled | Disaster recovery, high availability |
CDC | Moves only the records that changed | Real-time or near real-time | Keeping systems in sync without full reloads |
Reverse ETL | Sends warehouse data back to business applications | Scheduled or real-time | Putting analytics into CRM and marketing tools |
Let’s delve into each of these techniques in more detail:
1. Data Replication:
Data replication involves creating an exact copy of data from one location and moving it to another. This is used to ensure consistency between redundant resources, often in distributed systems. It’s commonly used in disaster recovery, as it ensures business continuity in case of system failures. Data replication also improves data availability, providing real-time data for analysis and enhancing system performance by distributing the load across multiple systems.
2. ETL:
ETL is a type of data movement where data is extracted from the source, transformed to fit operational needs, and then loaded into the target destination. The transformation process may involve the restructuring, cleaning, and formatting of data to align it with the standards and requirements of the intended target system or data warehouse. This phase ensures data consistency, quality, and compatibility. Finally, the loaded data, now transformed, is placed into the designated tables or structures within the target system, typically a data warehouse optimized for reporting and analytics.
3. ELT:
ELT is similar to ETL, but the order of operations is different. In ELT, data is extracted, loaded into a staging area, and then transformed. This method is particularly beneficial when handling large volumes of data, as it leverages the processing power of the target system, allowing for efficient and flexible transformations. ELT is well-suited for cloud-based data warehouses and big data solutions, where high processing power can expedite the data transformation process after loading.
4. CDC:
Change data capture (CDC) is a technique designed to identify and capture changes made to data over time. It tracks additions, updates, and deletions within a dataset, creating a log of modifications. CDC is particularly valuable for keeping data synchronized between source and target systems efficiently. By capturing only the changes made to the data, CDC minimizes the processing load and network bandwidth requirements, making it an effective strategy for real-time data integration and replication.
5. Reverse ETL
Reverse ETL moves data in the opposite direction: from the data warehouse back into the business applications teams use every day, such as CRM, marketing, and support tools. For example, a customer health score calculated in the warehouse can appear directly in a sales rep's CRM record. It closes the loop between analysis and action.
Data Movement vs. Data Integration vs. Data Migration
These terms overlap and are often used interchangeably, but they describe different things:
Term | What it means | Scope |
Data movement | Transferring data from one place to another, by any method | The umbrella term |
Data integration | Combining data from many sources into a unified, consistent view | Movement plus matching, cleaning, and transformation |
Data migration | Moving data permanently to a new system, often once | A project with a start and end date |
Data pipeline | The automated series of steps that moves and processes data | The mechanism that runs movement repeatedly |
Data migration deserves a closer look, because it is the most common reason organizations start moving data at scale.
Data migration is the process of moving data from one system, location, or format to another. This may be driven by factors such as system upgrades, cloud adoption, or the need to consolidate data from different sources. Data migration requires careful planning to ensure data integrity, consistency, and minimal downtime during the transition. The migration process often involves data cleaning to remove redundant, obsolete, or inaccurate data, ensuring that only high-quality, relevant data is moved to the new system. For tool options, see our comparison of the best data migration tools.
Purpose of Data Movement
With the rapid advancements in technology and the increasing volume of data generated by organizations, data movement has become a critical process. It plays a pivotal role in migrating data to modern systems as part of IT operations’ modernization and extension. As organizations upgrade their legacy systems to leverage advanced technologies, data movement ensures a seamless transition, preventing data loss and enabling full utilization of modern system capabilities.
Data movement finds its use in various scenarios within an organization. Here are some key use cases:
Data Archiving: Data archiving is the process of moving data that is no longer actively used to a separate storage device for long-term retention. Data movement comes into play here as it helps transfer this inactive data from primary storage systems to an archive. This frees up valuable space in the primary storage so that the archived data can be accessed and retrieved when needed.
Database Replication: This involves creating and maintaining multiple copies of the same database, often in different locations. Data movement is integral to this process as it ensures that any changes made to one database (like adding, modifying, or deleting data) are simultaneously reflected in all other copies. This maintains consistency across databases and enhances data availability and reliability.
Cloud Data Warehousing: Cloud data warehousing involves storing an organization’s data in a cloud-based data warehouse. Data movement is used to transfer data from the organization’s on-premises systems to the cloud warehouse. This not only provides the benefits of scalability and cost-efficiency associated with cloud storage but also enables real-time data analysis and insights.
Hybrid Data Movement: In a hybrid IT environment, organizations use a combination of on-premises and cloud-based systems. Hybrid data movement involves transferring data between these systems as needed. This way, data is always available in the right place at the right time, regardless of whether it’s stored on-premises or in the cloud.
Real-time analytics: Streaming changes from operational systems into analytics platforms lets teams spot problems as they happen, such as a spike in failed payments or a stock shortage, instead of waiting for the next nightly load.
Application synchronization: Keeping records such as customers, orders, and inventory consistent across the ERP, CRM, and ecommerce platform, so every team works from the same numbers.
Benefits of Data Movement
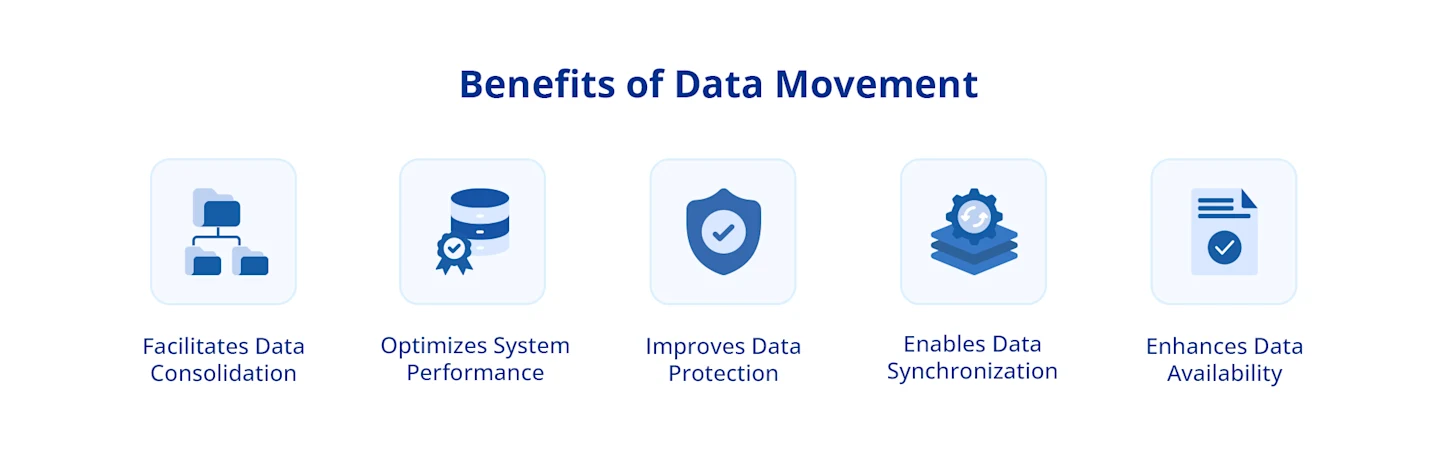
Data movement offers several benefits to an organization and contributes to the overall efficiency and effectiveness of its data management strategy. Here are some key benefits:
Facilitates Data Consolidation: Data movement allows organizations to consolidate data from various sources into a single, unified system. By simplifying data management, it ensures consistency and accuracy of data, and provides a comprehensive view for better decision-making.
Optimizes System Performance: Data movement enhances system performance by managing data load effectively. It transfers inactive or seldom-used data from primary to secondary or archive storage, reducing the burden on the primary system and improving system speed and efficiency.
Improves Data Protection: Data movement is integral to the process of data backup and recovery. By creating backups of data, organizations can safeguard their data against potential loss or damage due to system failures or data breaches, enhancing data security and ensuring business continuity.
Enables Data Synchronization: In a multi-cloud or hybrid cloud environment, data movement helps synchronize data across different platforms, ensuring that all systems have the most up-to-date and consistent data, thereby improving data reliability.
Enhances Data Availability: In the context of database replication, data movement ensures that data is consistently available across multiple locations, enhancing data availability and reliability, particularly in distributed systems.
Risks Involved in Data Movement
While data movement is crucial for many aspects of data management and IT operations, it does come with certain risks. Here are some of the potential risks involved in data movement and the ways in which they can be overcome:
Data Loss: One of the most significant risks while moving data between systems is data loss, which can occur due to multiple reasons, such as technical glitches, human error, or system failures. To mitigate this risk, it’s crucial to have a robust data backup strategy in place. Regular backups ensure that a recent copy of the data is always available for recovery.
Data Breaches: Moving data sets, particularly sensitive ones, can expose them to potential security threats. If not properly secured, data could be intercepted during transit, leading to data breaches. To prevent data breaches, organizations should take measures to encrypt their data during transit. Additionally, secure data transfer protocols should be used, and access to the data should be strictly controlled.
Data Corruption: Data can get corrupted during the movement process due to various reasons, such as software bugs, hardware failures, or sudden power outages, rendering it unusable. One way to this is to perform data integrity checks before and after the data movement process. Any discrepancies should be immediately addressed to ensure the accuracy of the data.
Schema changes: When a source system adds, renames, or removes a column, pipelines can fail or silently load the wrong data. Monitor source schemas and set alerts so changes are caught before they reach reports.
Compliance Violations: If data is not moved in compliance with data protection and privacy regulations, it can result in legal penalties and damage to the organization’s reputation. Organizations should be well-versed with relevant regulations and ensure that their data movement processes are compliant.
Downtime: Data movement, particularly large-scale data migration, can lead to system downtime, disrupting business operations. However, most downtimes can be avoided by scheduling data movements during off-peak hours. Also, using a phased migration approach where data is moved in small batches helps keep the transition smooth.
The Need For a Data Movement Tool & How to Select One?
Organizations today handle data that’s not only increasing in complexity but also in size, necessitating the need for data movement tools. With data often scattered across various sources and systems, a data movement tool helps consolidate and integrate this data, ensuring it’s available where and when it’s needed. These tools also facilitate the seamless migration of data during system upgrades, optimize storage management through data archiving, and enhance data availability in distributed systems.
Choosing the right data movement tool is a critical decision that can significantly influence an organization’s data management capabilities. Here are some specific factors to consider:
Data Connectivity: The tool should be able to connect to various data sources, both on-premises and cloud-based. At the same time, it should support different data types and formats.
Scalability: As an organization’s data volume grows, the tool should be able to scale to meet these increasing needs. It should be able to handle data volume without compromising performance.
Compatibility: The solution should be compatible with the organization’s existing systems and platforms. It should be able to handle the types of data sources the organization works with and support the data formats in use.
Security: Given the sensitive nature of data, the data movement tool should have robust security features. This includes encryption for data in transit, secure access controls, and compliance with relevant data security standards.
Real-Time Data Movement: For businesses requiring real-time insights, the tool should be capable of moving data in real-time or near real-time.
Monitoring and alerts: Look for built-in job monitoring, logs, and alerts, so failed or delayed runs are caught before anyone relies on stale data.
Ease of use: A no-code, visual interface lets more of the team build and maintain data flows, instead of queuing every change behind a few engineers.
Support and Documentation: When dealing with complex data movement tasks or troubleshooting issues, it is crucial to look for a solution that provides comprehensive customer support and documentation to provide the necessary assistance.
Conclusion
As businesses continue to evolve and expand, the volume, velocity, and variety of data they handle are set to rise exponentially. This makes data movement an increasingly crucial aspect of any data management strategy. Effective data movement ensures that data from various sources is consolidated, transformed, and made readily accessible for real-time decision-making. Although it does not inherently play a direct role in maintaining data quality and ensuring regulatory compliance, it does offer the opportunity to account for these processes, facilitating seamless data integration.
Astera, with its comprehensive suite of features, is an effective data movement tool. It seamlessly integrates with existing systems, offering robust data transformation capabilities, extensive connectivity options, and near real-time data movement, making it a reliable choice for businesses of varying sizes.
By integrating Astera into their data management strategy, organizations can effectively navigate their current data landscape and prepare for the future, thereby enhancing operational efficiency and overall business performance.
Try Astera out with a free 14-day trial today and elevate your data management strategy!
Start Your Data Movement Journey Today
Leverage Astera's extensive connectivity options that enable seamless integration with a variety of platforms, databases, and applications, facilitating smooth and effective data movement across diverse systems.
