

Data Provenance vs. Data Lineage
Two related concepts often come up when data teams work on data governance: data provenance and data lineage. While they may seem similar at first glance, there are fundamental differences between the two concepts.
Data provenance covers the origin and history of data, including its creation and modifications. On the other hand, data lineage tracks the data’s journey through various systems and processes, highlighting its flow and transformation across different data pipeline stages.
What is Data Provenance?
Data provenance is the origin and history of a piece of data. It involves recording data creation and details of applied changes – for example, when the data was modified and by whom. Data provenance aims to provide a complete picture of how the data came to be, including the processes it went through and any changes made along the way.
Data provenance answers questions like: What is the source of this data? Who created this data? What changes, if any, were made to this dataset? This information helps ensure data quality, transparency, and accountability.
This knowledge is particularly valuable in highly regulated industries, such as healthcare or banking, where data trust is essential for compliance.
Why is Data Provenance Important?
Data provenance allows analysts to identify corrupted data on time. For example, in the case of a data breach, having a robust data provenance system in place can help determine the point of entry and the extent of the breach, enabling swift and targeted responses to mitigate the impact.
This proactive approach enhances the overall trust in the data and streamlines data validation processes. Plus, according to the 1:10:100 rule of data quality, it costs only $1 to prevent low-quality data from damaging decision-making – and $10 for correcting errors and $100 for doing nothing.
Organizations can assess the data’s reliability and trustworthiness by understanding the origin and history of data. This information is crucial when dealing with sensitive data, as it helps maintain data privacy.
Data provenance also supports data collaboration and sharing. When multiple teams or organizations work with the same data, clearly understanding its provenance fosters trust, facilitates collaboration, and reduces redundancy.
Examples and Use Cases of Data Provenance
Some examples and use cases to better understand how data provenance can be applied in various industries:
Healthcare: Data provenance enables healthcare providers to maintain an accurate record of patient’s medical history, which is vital to deliver the expected level of patient care. It also helps improve and maintain the integrity of healthcare research by ensuring researchers understand how data is collected and analyzed. For instance, tracking the provenance of medical records can help identify any changes made to the data, ensuring data integrity and accuracy.
Financial institutions: Banks must ensure regulatory compliance and effective risk management in the financial sector. Visibility into the source and movement of financial data, such as transaction records, enables them to ensure that it has not been tampered with. This transparency reduces fraud and ensures the accuracy and reliability of financial reports.
Education: Data provenance also plays a significant role in educational institutes. With the increasing use of technology in classrooms, educators rely on data to assess student performance and tailor instruction accordingly. By tracking the provenance of educational data, such as test scores and learning analytics, educators can gain insights into students’ progress over time, identify areas of improvement, and personalize their teaching strategies. This empowers educators to provide targeted support and enhance student learning outcomes.
What is Data Lineage?
Data lineage focuses on the flow and transformation of data from its source to its destination. It is concerned with understanding how data moves and changes as it is processed, refined, and integrated into various systems and applications. In short, data lineage provides a detailed record of the data’s journey through these systems.
In a sense, data lineage expands upon data provenance.
Data lineage shows the impact of data transformations on downstream processes and decisions. It helps answer questions like “Which datasets were used to generate this report?” and “What extract, transform, and load (ETL) processes were applied to the data?”. By mapping the lineage of data, organizations can uphold the accuracy and reliability of analytics, reporting, and decision-making processes.
Why is Data Lineage Important?
Data lineage is crucial for data governance, data management, and regulatory compliance. It ensures transparency and accountability by providing visibility into the entire data flow and transformations.
Moreover, data lineage plays a vital role in enhancing data security. Organizations can better monitor and protect sensitive information by tracking the data flow from source to destination.
Another aspect of data lineage is its role in enhancing data quality—it helps pinpoint where data health issues arise. Without lineage, data teams will easily spend hours sifting through transformations to find the root cause.
By visualizing the flow of data from its origin to its consumption, data lineage tools enable data stewards and analysts to identify potential bottlenecks, inconsistencies, or errors in the data pipeline. This visibility allows for proactive data management strategies, such as data cleansing, standardization, and enrichment, to be implemented, ultimately improving the quality and reliability of data-driven insights and business decisions.
Examples and Use Cases of Data Lineage
Business intelligence (BI) and reporting: Data lineage ensures accurate and trustworthy reports and dashboards. It allows organizations to understand how the data used in these reports was sourced, transformed, and aggregated.
Regulatory compliance: Finance, healthcare, and insurance industries have strict compliance requirements. Data lineage provides an audit trail of the data used in regulatory reports or calculations, which helps demonstrate regulatory compliance.
Data governance and data stewardship: Data lineage is a valuable tool for data governance and stewardship initiatives. It helps organizations understand the effect of changes to their data infrastructure or data policies on downstream processes and applications. By mapping the data lineage, organizations can identify any risks, dependencies, or data quality issues that must be addressed.
Data Provenance vs. Data Lineage: Key Differences
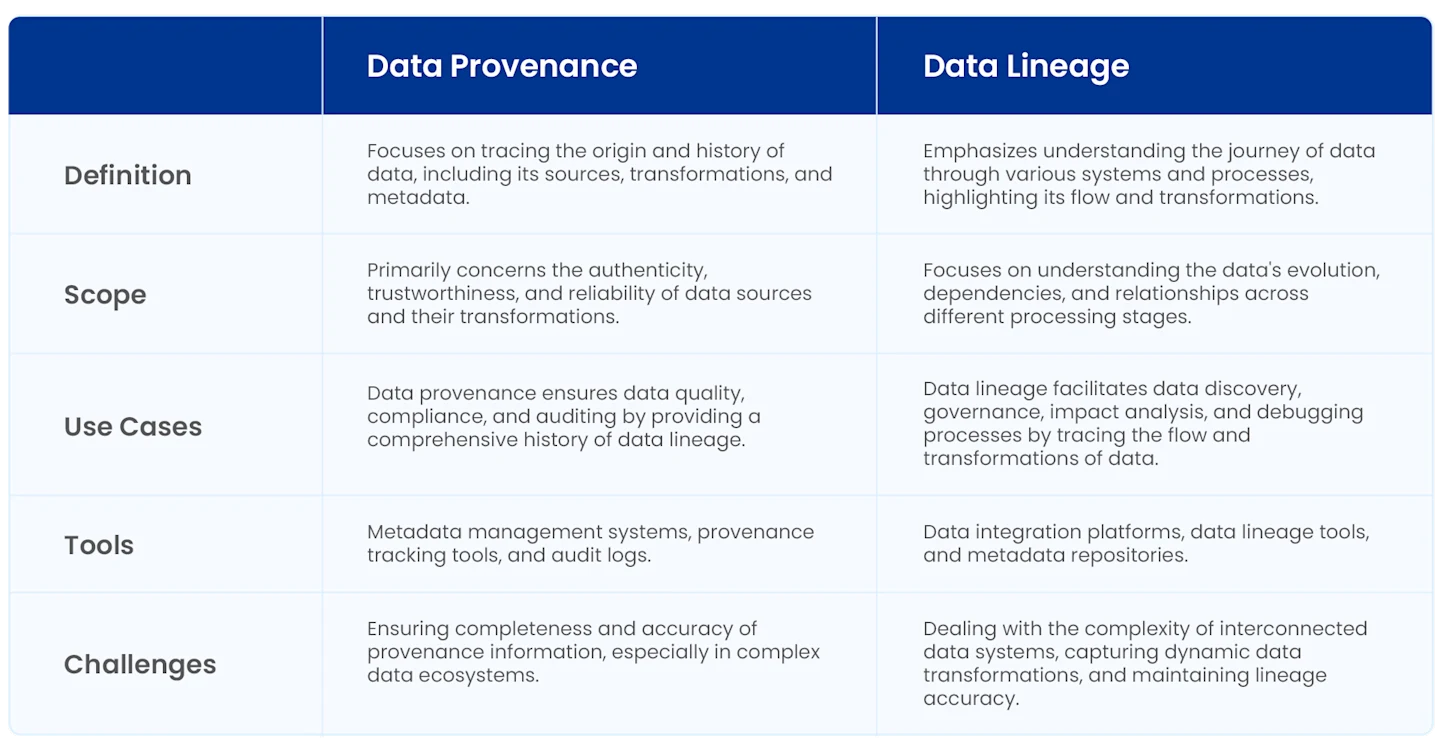
Now that we have explored data lineage and data provenance, it is important to understand their key differences.
The main distinction between data provenance and lineage lies in their focus and scope. Data provenance emphasizes the origin and history of a piece of data, tracking its sources and transformations. It focuses on the “breadcrumb trail” of a specific data element, providing valuable insights into its quality, reliability, and accountability.
On the other hand, data lineage focuses on the flow and transformation of data as it moves through different systems and processes. It provides a holistic view of how data is transformed, aggregated, or joined, enabling organizations to understand the impact of these transformations on downstream processes and decisions.
Should you Prioritize Data Provenance or Data Lineage?
Prioritizing one over the other depends on your organization’s specific needs and goals.
Data provenance should be a priority if your primary concern is ensuring data quality, reliability, and compliance. Tracking the origin and transformations of data helps identify potential issues, ensure accountability, and meet regulatory requirements.
On the other hand, if your focus is on understanding the impact of data transformations on downstream processes and decision-making, data lineage is key. By mapping the flow and transformations of data, you can assess the reliability of analytics, reports, and data-driven decisions.
However, it’s important to note that these concepts are closely connected in many cases, with data provenance forming the foundation for data lineage. Both data provenance and data lineage are essential features of a comprehensive data management and governance strategy. So, it’s not about choosing one over the other. It’s about finding a balanced approach that considers both provenance and lineage in data management and analysis. This way, you can address your data’s origins and history (provenance) and its flow and relationships (lineage).
Implementing both data provenance and data lineage can provide a comprehensive understanding of your data assets and enable efficient data governance and decision-making.
Why Data Provenance Matters More in the Age of AI
As more organizations train, fine-tune, and evaluate AI models on their own data, data provenance has taken on a new and urgent role. Knowing exactly what data went into a model — where it came from, whether it was properly licensed or consented, and how it was transformed before training — is no longer just a data-quality nicety. It's becoming a governance and, increasingly, a legal requirement.
This shows up in a few concrete ways:
Training data transparency — being able to show regulators, customers, or auditors exactly which datasets fed into a model.
Bias and quality investigation — when a model produces skewed or incorrect outputs, provenance lets teams trace the problem back to the specific data, and its history, that caused it.
Consent and licensing — confirming that data used for training stayed within its original consent or license terms.
Data lineage still matters here too — it's what shows how raw data moved through preprocessing and feature pipelines before reaching a model. But provenance is what lets an organization vouch for the data itself, which is exactly why it's the concept getting the most attention as AI governance frameworks mature.
Best Practices for Implementing Data Provenance and Lineage
Implementing data provenance and data lineage requires careful planning and consideration. Here are some best practices to help you get started:
Clearly articulate your organization’s data provenance and lineage requirements. Understand the specific questions you need to answer and the outcomes you want to achieve.
Focus your efforts on tracking the provenance and lineage of mission-critical data elements.
Document and capture detailed information about the processes, systems, and transformations throughout the data lifecycle to understand the lineage and provenance of your data.
Leverage automation tools and technologies for tracking data provenance and lineage to minimize human error risk and ensure consistent and accurate documentation.
Identify and consult key stakeholders early on in the process to account for their needs and requirements and ensure that the implementation aligns with the organization’s wider goals.
Your data provenance and lineage framework should be able to handle the additional complexity and scale seamlessly as your organization grows and the volume of data increases. Consider using advanced technologies such as distributed ledger technology or cloud-based solutions that can accommodate the growing demands of your data ecosystem.
Conduct regular audits and data quality checks to validate the accuracy and reliability of your data. Use the information captured through data provenance and lineage to identify discrepancies, outliers, or anomalies.
Data provenance and lineage are not one-time initiatives. Continuously refine and enhance your data management processes based on the insights from tracking the provenance and lineage of your data.
Conclusion
Data provenance and data lineage are critical concepts in data governance and management that provide valuable insights into the origin, history, and flow of data. While they share a common goal of enhancing data quality, accountability, and decision-making, their focus and scope differ. The optimal strategy for data teams is to find the right balance. They can look into incorporating modern data solutions that offer various governance features.
Astera is a no-code enterprise data management platform that offers lineage and impact analysis for data assets. It enables business users to easily track and govern their data with robust features and a simple, user-friendly UI that’s easy to use even for business users. Astera also provides an AI-powered business glossary, data enrichment, profiling, and a Data Marketplace for effective data governance.
Are you looking to implement a comprehensive data governance strategy in your company? Let us help you by contacting us.