

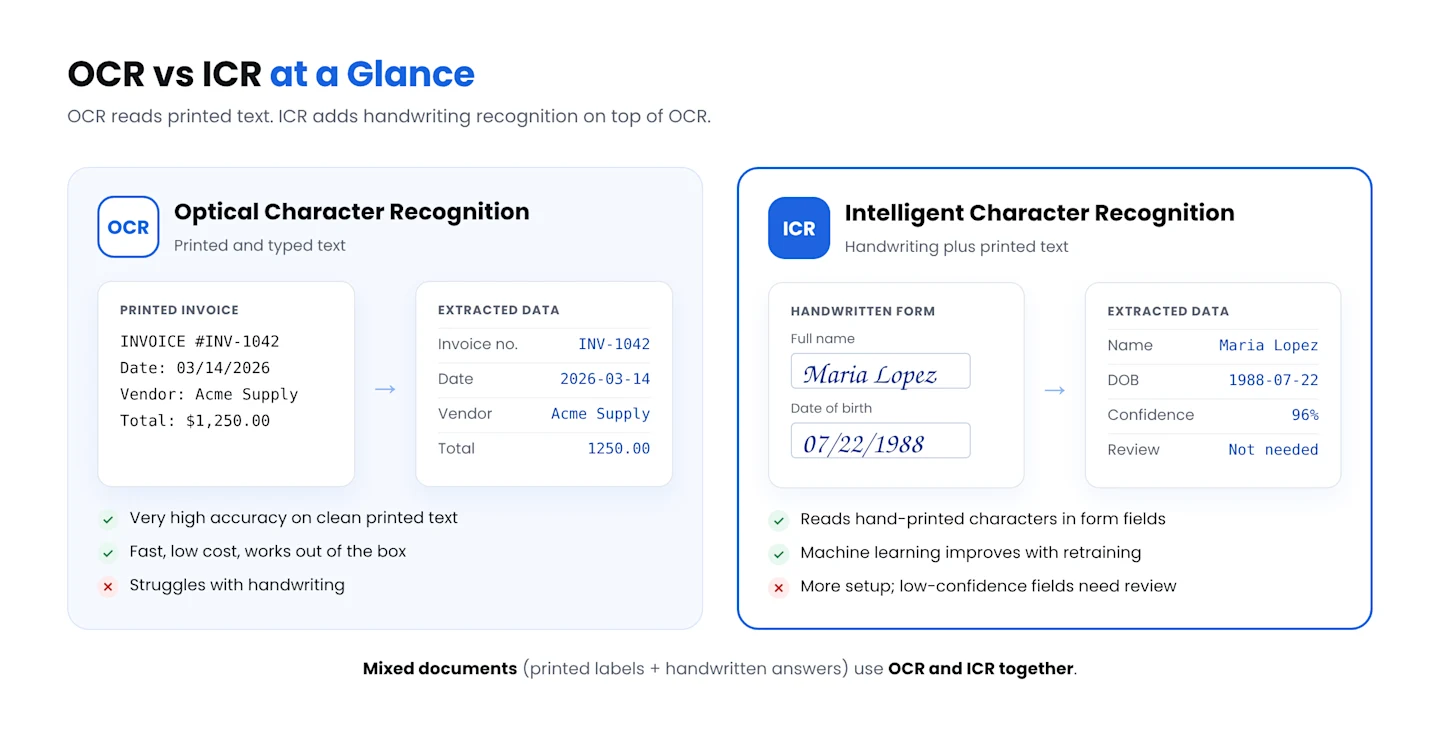
The main difference between OCR and ICR is the kind of text they read. OCR (optical character recognition) converts printed or typed text into machine-readable data. ICR (intelligent character recognition) goes further and reads handwriting, using machine learning to handle different writing styles.
If your documents are mostly printed, such as invoices, contracts and bank statements, OCR is usually enough. If they include handwritten entries, such as filled-in forms, patient intake sheets and survey responses, you need ICR. Many real-world documents contain both, which is why modern document processing tools combine the two.
Below, we compare OCR and ICR side by side on accuracy, handwriting support, cost and use cases, with examples of which technology fits which document.
What is OCR?
OCR is a well-established technology that converts printed text into digital data. It recognizes characters in scanned images or documents and turns them into editable text. This is especially useful for digitizing documents like invoices, reports, and other printed materials.
OCR works best when the text is printed clearly in standard fonts. However, its accuracy can decrease with distorted text or unusual fonts. If you're processing large volumes of printed content, OCR can save significant time and effort by converting paper-based information into searchable digital formats.
When to use OCR
OCR is the ideal choice when your documents consist of clearly printed text, such as:
Business documents like invoices, contracts, or letters
Scanned reports or articles
Official forms with pre-printed fields
Read more: IDP vs. OCR
What is ICR?
ICR is an advanced version of OCR designed to handle more complex documents, particularly those with handwritten text. It leverages artificial intelligence (AI) and machine learning algorithms to analyze and recognize a wide range of handwriting styles, making it more versatile than traditional OCR.
While OCR excels with printed text, ICR is better suited for documents that include handwritten fields, such as forms or surveys. Its ability to improve accuracy as it processes more documents makes it a powerful tool for industries dealing with a mix of printed and handwritten data.
When to use ICR
ICR is best for documents with handwritten content or those where text recognition is more challenging, such as:
Handwritten forms, surveys, or customer feedback
Medical records and applications
Documents with signatures, annotations, or notes
OCR vs. ICR: Summarizing the differences
While both OCR and ICR serve similar functions—extracting data from documents—they are designed for different types of content. Here's a direct comparison:
Factor | OCR (Optical Character Recognition) | ICR (Intelligent Character Recognition) |
|---|---|---|
What it reads | Printed and typed text in standard fonts | Handwritten text (usually hand-printed characters) plus printed text |
Handwriting support | Little or none; handwriting usually produces errors | Yes; designed for handwriting and works best on block letters written in boxed fields |
Cursive | No | Limited; full cursive words need intelligent word recognition (IWR) or AI-based models |
Accuracy on clean printed text | Very high | Very high (uses OCR for printed text) |
Accuracy on handwriting | Low | Moderate to high, depending on how neat the writing is and how the form is designed |
How it works | Matches character shapes against known fonts and patterns | Neural networks trained on many handwriting samples |
Improves over time | Not on its own; fixed models or templates | Yes, when retrained on corrected samples |
Sensitivity to scan quality | High; skew, blur and low resolution reduce accuracy | Very high; messy writing and poor scans both add errors |
Setup effort | Low; works out of the box on most printed documents | Higher; often needs form templates, field zones and validation rules |
Cost | Lower; widely available, including free and open-source engines | Higher; licensed engines and more processing power |
Speed | Fast | Slower per page because of heavier processing |
Human review needed | Low on clean documents | Moderate; low-confidence fields are usually routed to a person to check |
Typical documents | Invoices, purchase orders, contracts, bank statements, printed reports | Application forms, claim forms, patient intake sheets, surveys, delivery notes |
Common industries | Finance, legal, logistics, publishing | Healthcare, insurance, government, banking, education |
OCR vs ICR: Examples by Document Type
Document | Content | Best fit | Why |
|---|---|---|---|
Supplier invoice (PDF or scan) | Printed text and tables | OCR | Everything is printed, so OCR captures header fields and line items without handwriting models. |
Bank statement | Printed text and tables | OCR | Consistent printed layouts and dense tables are a strong match for OCR with table detection. |
Patient intake form | Pre-printed labels + handwritten answers | OCR + ICR | OCR reads the printed labels; ICR reads the patient's handwritten answers in each field. |
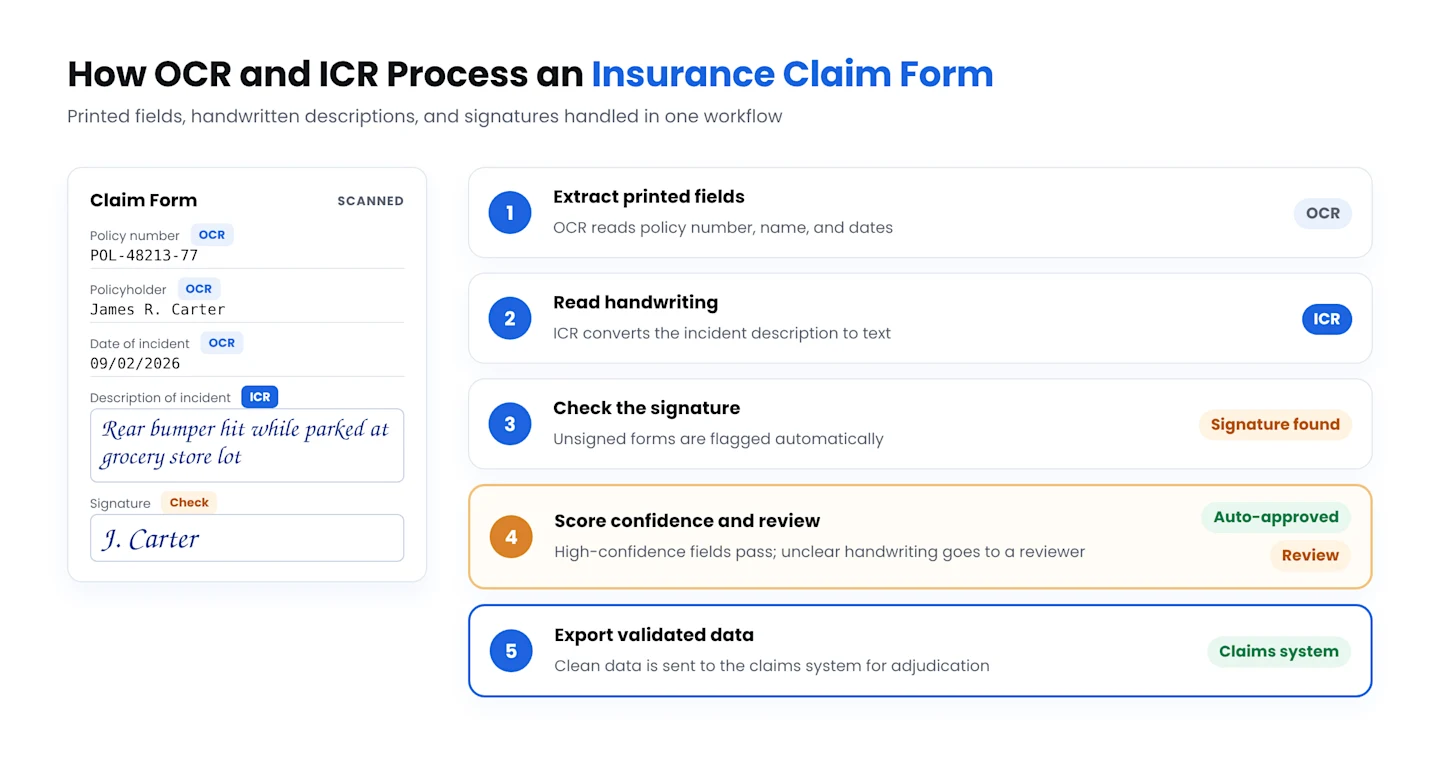
Insurance claim form | Printed form + handwritten damage description | OCR + ICR | Policy fields are printed, but the incident description is written by hand and needs ICR. |
Customer survey card | Checkboxes + handwritten comments | ICR + OMR | OMR (optical mark recognition) detects ticked boxes; ICR reads the free-text comments. |
Handwritten check | Printed MICR line + handwritten amount | MICR + ICR | MICR reads the magnetic-ink account and routing numbers; ICR reads the handwritten amount and payee. |
Delivery note with signature | Printed details + handwritten notes and signature | OCR + ICR | OCR captures order details; ICR reads notes, and signature detection confirms the delivery was signed. |
Typed contract | Printed text, many pages | OCR + NLP | OCR digitizes the text; NLP finds clauses, parties, dates and amounts across long documents. |
Worked example: an insurance claim form
A claims team receives 5,000 scanned claim forms a month. Each form has:
printed policy fields
a handwritten description of the incident
a signature
With OCR alone, the printed fields come through cleanly, but the handwritten descriptions come out garbled and must be typed by hand. With OCR and ICR combined:
The printed fields are extracted automatically.
ICR reads the handwritten descriptions.
The system checks that a signature is present and flags unsigned forms.
Each field gets a confidence score. High-confidence fields pass straight through, while low-confidence ones, such as hard-to-read handwriting, are routed to a reviewer.
Validated data is exported to the claims system, ready for adjudication.
Instead of typing every description by hand, the team only reviews the small share of fields the system isn't sure about. That shortens processing time and keeps people focused on the claims that need judgment.
Advanced technologies related to OCR and ICR that simplify document processing
While OCR and ICR are essential tools, they aren't the only options available for automating document processing. Several emerging technologies can help businesses further streamline data extraction and improve accuracy.
Intelligent document processing (IDP)
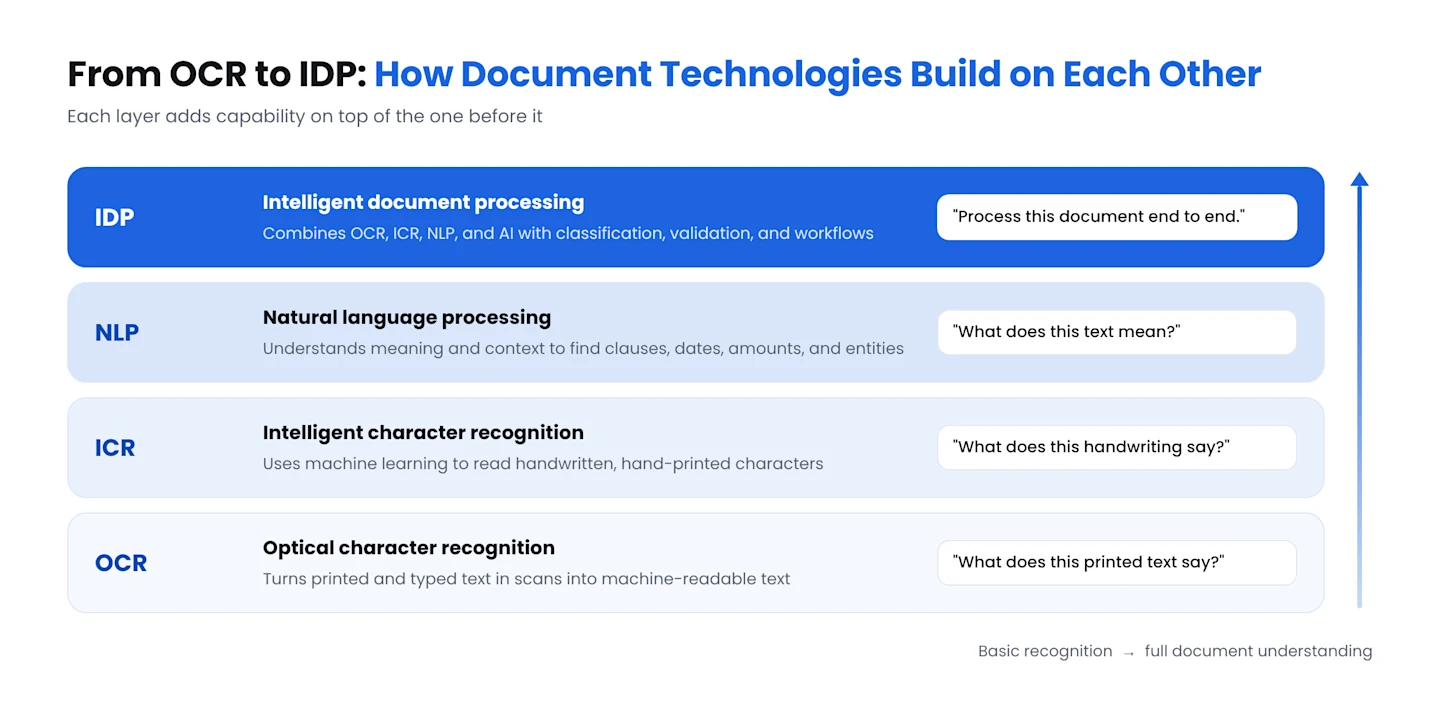
IDP integrates OCR, ICR, and AI to automate and optimize document classification, data extraction, and workflow management. It's especially effective for handling unstructured data, such as emails or documents with mixed content. IDP goes beyond simple recognition and uses AI to understand the context of the text.
Using an IDP solution, your teams can automatically extract data from invoices while also extracting signatures or handwritten notes and categorizing the document type (e.g., invoice, receipt) in one seamless process.
Use AI to automatically process multiple documents with varying layouts
Astera offers an AI-powered document processing solution that enables you to extract data from hundreds of document in minutes. All you have to do is specify the data you need and Astera Intelligence does the rest. Try Astera for free.

Machine learning-based data extraction
Machine learning algorithms are increasingly capable of handling complex document types. Unlike traditional OCR and ICR, which rely on predefined rules, machine learning-based data extraction systems automatically adapt and refine their performance as they process more documents.
Their ability to learn from a variety of document formats and layouts allows them to continuously improve, making them particularly effective for handling diverse and dynamic content. This means that machine learning models can also help improve the accuracy of OCR and ICR systems by learning to recognize variations in document fonts and handwriting styles.
Natural language processing (NLP)
NLP enhances data extraction by analyzing text for meaning and context, helping to automatically classify, extract, and interpret data more intelligently. It can be especially useful for extracting specific information from unstructured documents like legal contracts or customer feedback.
While OCR and ICR focus on converting text, NLP can help make sense of that text if used in tandem. For instance, it can identify key data points like dates, amounts, or terms in unstructured documents, improving the accuracy of data extraction from complex documents.
Large language models (LLMs)
Newer AI document tools use large language models and vision-language models to read a page more like a person would. Instead of recognizing characters one by one, they interpret the whole page, including layout, labels, and context. This helps with cursive handwriting, unfamiliar layouts, and fields that don't sit in fixed positions. As with ICR, results should still be validated with business rules and human review for low-confidence fields.
OCR vs. ICR: Choosing the right technology
The decision to use OCR or ICR primarily depends on the nature of your documents. OCR is perfect for straightforward, printed text, while ICR shines with handwritten or mixed-content documents. However, if your organization deals with large volumes of varied content, consider integrating an AI-powered document processing solution, such as Astera, for enhanced accuracy and efficiency.
A quick way to decide:
Choose OCR if nearly all of your documents are printed or digital PDFs, such as invoices, statements, and contracts.
Choose OCR + ICR if your forms mix printed labels with handwritten entries.
Choose an IDP platform if you process many document types and layouts and need classification, validation, and export to other systems in one workflow.
Streamline document processing with Astera
Processing documents and extracting data is a breeze with Astera's AI-document processing platform. From claims forms to shipping documents to medical records, all you have to do is specify the fields and Astera Intelligence (AI) will automatically extract the data accurately.
What truly sets Astera apart is the ability to build AI-powered pipelines that automate the entire document processing workflow from end to end. Contact us and discuss your use case today.