

The class of 2027 saw a massive influx of applications at top universities across the United States. Harvard received close to 57,000 applications for the class of 2027, while MIT received almost 27,000. UC Berkeley and UCLA, meanwhile, received 125,874 and 145,882 respectively.
Manual transcript processing is an uphill battle for educational institutions at every level. With students’ academic futures at stake, admissions staff must quickly process every transcript, document, and form — ensuring accuracy and adherence to tight deadlines.
When the sheer volume of applications is combined with short turnaround times, it can result in a concerning rise in mistakes, inefficiency, and delays. However, modern automated transcript processing solutions, with AI-driven data extraction at their core, are a powerful solution to this problem.
Benefits of Automated Transcript Processing
Faster Processing
Manual handling, input, and processing of transcripts take considerably longer to complete, creating otherwise avoidable delays. Automated solutions can perform similar tasks in less time, improving efficiency.
Fewer Errors
Manual data processes are vulnerable to human errors, such as incorrect entries and wrong calculations to transposition mistakes. Automated transcript processing decreases errors and ensures more accurate transcript data.
Better Scalability
Manual transcript processing offers limited scalability. In contrast, educational institutions can readily scale automated transcript processing solutions as needed. This eliminates bottlenecks and enables smooth functioning.
Resource Optimization
AI-powered data extraction tools automate repetitive tasks, such as data entry and validation. This enables personnel to focus on more complex areas where human involvement is necessary—such as student counseling, curriculum development, and academic research.
Compliance
Regulations such as the General Data Protection Regulation (GDPR) and the Family Educational Rights and Privacy Act (FERPA) are applicable to academic institutions. AI-powered data tools help ensure compliance and keep data safe through measures such as anonymization and encryption.
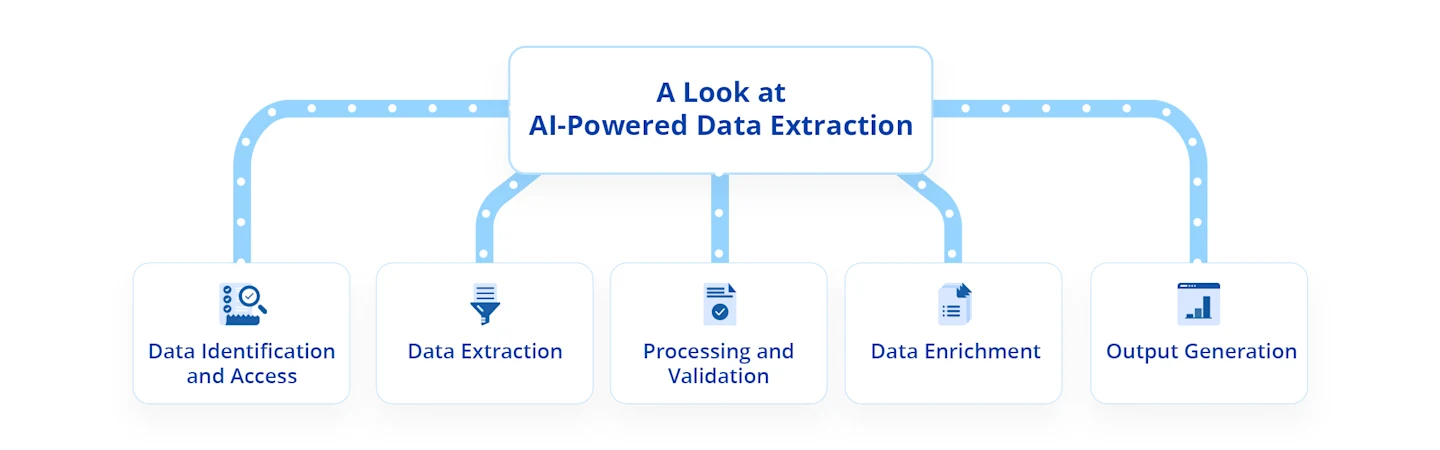
A Closer Look at AI-Powered Data Extraction
AI-powered data extraction tools are ideal for automating transcription processing. They are less resource-intensive and require little to no human intervention. Automated data extraction and processing includes the following steps:
1. Data Identification and Access
The process begins by identifying the sources of information, which range from documents and databases to web services and emails. Once identified, these sources are accessed through direct database connections, Application Programming Interfaces (APIs), or other methods for obtaining the data.
2. Data Extraction
Different kinds of data extraction techniques are used depending on the purpose. Some of the most used extraction techniques used in education include:
Pattern Matching: Pattern matching entails identifying specific patterns or sequences in data. In education, pattern matching enables data extraction from data sources like course syllabi, student records, or test scores, followed by trend identification in student performance and anomaly detection in assessment data.
Natural Language Processing: NLP techniques allow the analysis and understanding of human language. In education, NLP helps with sentiment analysis of student feedback, educational content summarization, and automatic grading of written work.
Named Entity Recognition: As a subset of NLP, NER entails identifying and categorizing named entities (such as people or locations) within text data. In education, NER can be used to extract author names from academic papers, names of institutions from a research paper, or student and faculty names from an administrative document.
Machine Learning Models: Machine learning models include supervised, semi-supervised, and unsupervised learning algorithms. In the education sector, these models can be trained for predictive modeling, creating recommendation systems, performing clustering and segmentation, and topic modeling.
3. Processing and Validation
Following extraction, data is parsed into a structured format for further processing or analysis, an example of which is filtering data based on some criteria. For instance, users can filter data to only see the details of students registered in 2023. Data quality checks are implemented to validate the data and ensure it’s aligned with what’s required.
4. Data Enrichment
Data enrichment steps are optionally performed to enhance the extracted data. For example, text data is annotated, or extracted records are linked to external databases.
5. Output Generation
In the final step, extracted and processed data is shared as a structured database, spreadsheet, or custom report. Customizable output formats ensure that the data remains usable for end users’ needs or downstream applications.
What to Look for in an Automated Transcript Processing Tool
1. Accuracy
Accuracy is the most important factor when working with academic transcripts. The right tool should be highly accurate in recognizing and processing transcripts. It should correctly capture information such as course titles, credits, grades, and other details to ensure reliability.
2. Robust Data Extraction Capabilities
Features such as optical character recognition (OCR), template-based extraction, natural language processing (NLP) and data parsing algorithms signify that a tool has reliable data extraction processes.
3. Customization Options
Customization options can configure a tool’s transcript processing workflow to individual requirements. Useful customization features include options to create custom data fields, modifying extraction parameters, and reconfiguring validation rules as needed.
4. Data Security and Compliance
Adherence to rigorous data security standards and compliance regulations is a must-have for any automation tool. These tools process massive amounts of sensitive student information, and need to have encryption, access control and other security procedures in place to keep this information safe.
5. Ease of Use and User Interface
Complicated tools are difficult to understand and use. For a transcript processing tool to have maximum usability, it should have features like an intuitive, user-friendly interface, drag-and-drop functionality and highly customizable workflows for simpler transcript processing and increased productivity.
Take Your Transcript Processing Up a Notch
Faster, error-free, scalable, and optimized. Astera's AI-powered data extraction capabilities don't just automate your transcript processing — they transform it! Learn more today.

Streamlining Transcript Processing Using Astera
Astera is a no-code, automated solution simplifies data extraction, processing, validation, and transfer to various destinations. It can handle different kinds of documents—including transcripts.
It uses a template-based extraction model to extract pertinent data from unstructured sources/documents. To do so, all it needs is a user-defined customized data extraction template, also called a Report Model.
Astera’s no-code interface ensures that even the non-technical administrative staff in an academic institution can operate it easily. The outcome is a more streamlined and efficient transcript processing system.
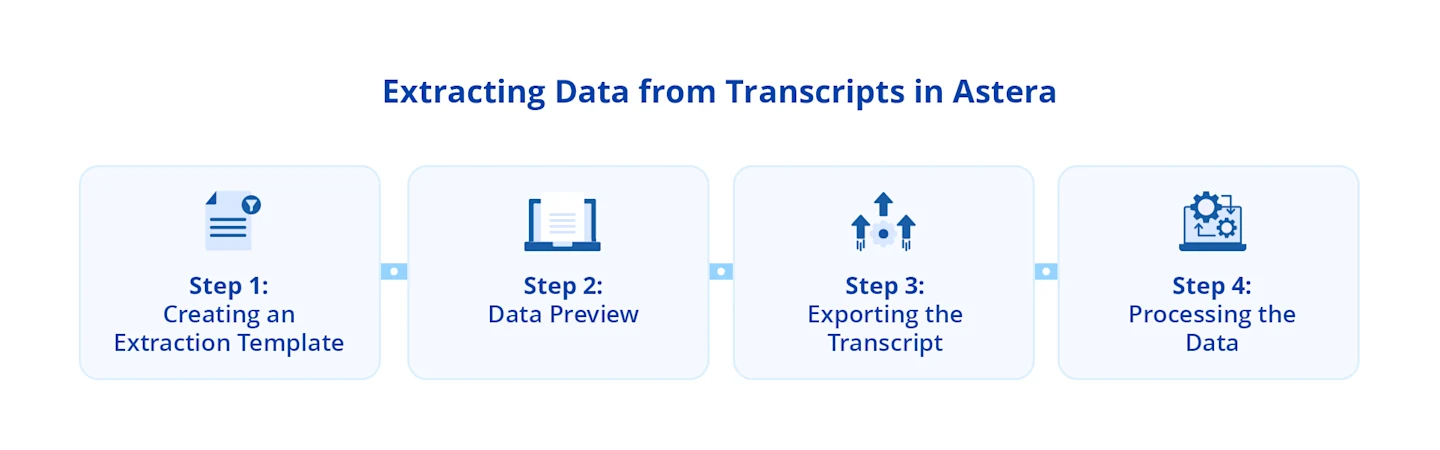
A Step By Step Guide to Extracting Data from Transcripts
The Extraction Template
The first step in processing transcripts using Astera is the creation of an extraction template. This template ensures that all pertinent information is accurately captured. For this use case, let’s start with the sample transcript (in PDF format) below:
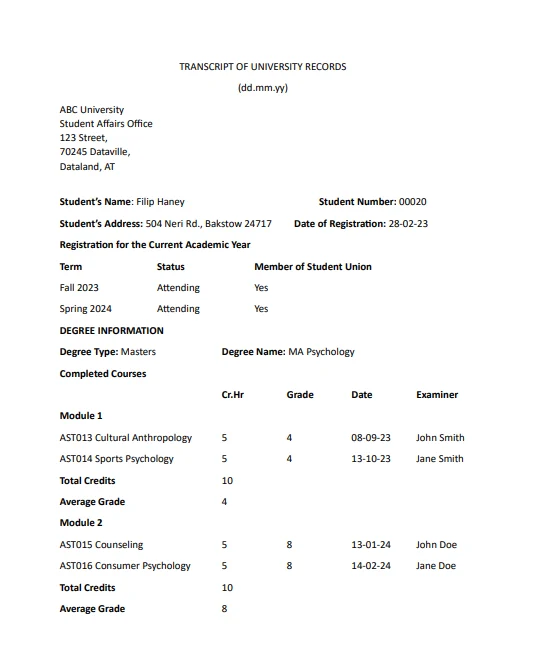
Loaded into Astera, the transcript above will look like this:
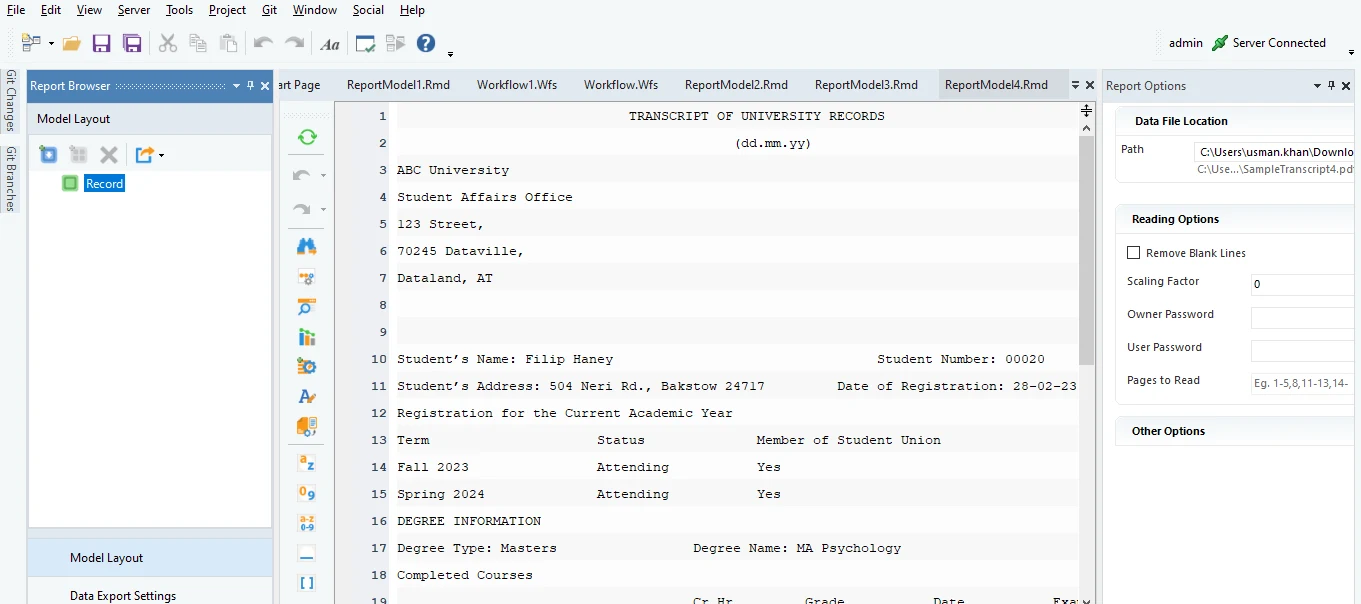
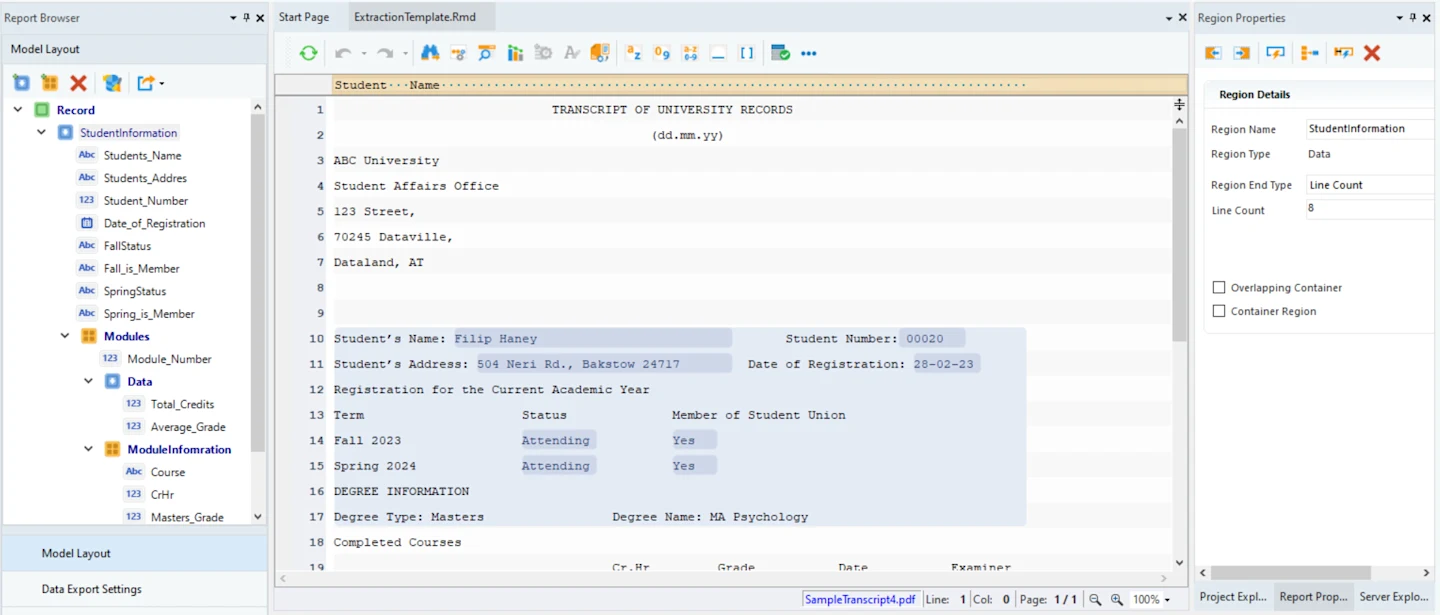
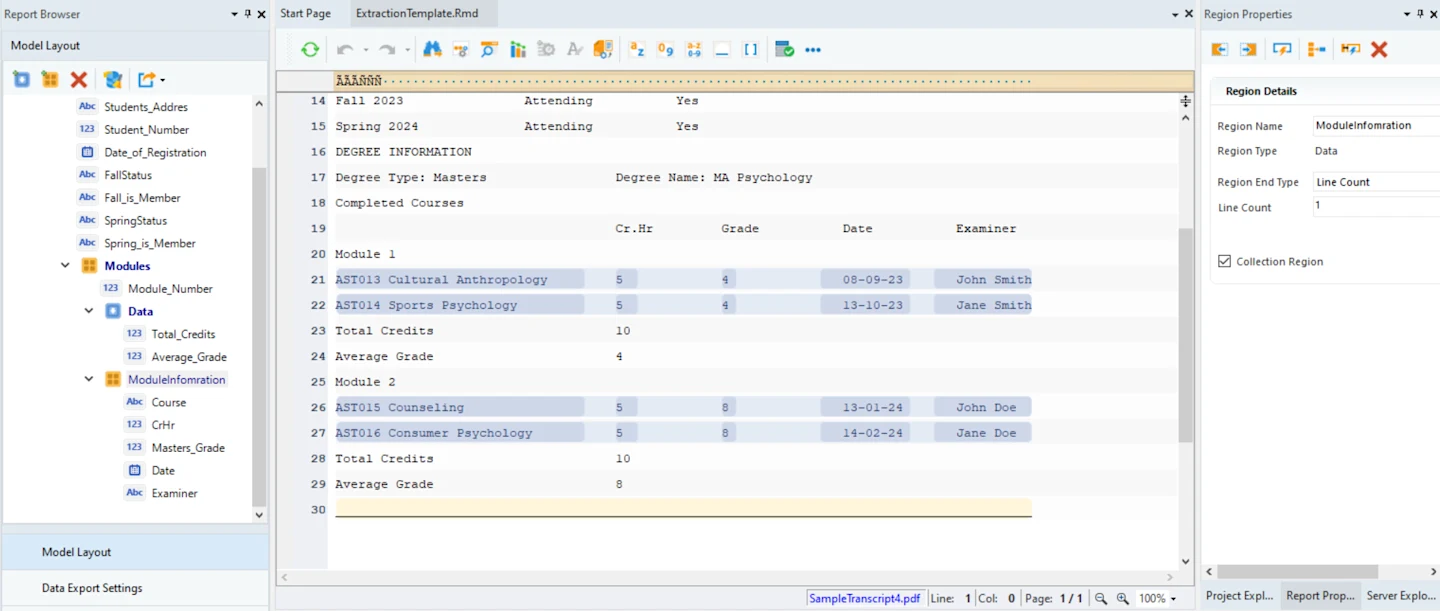
After loading a document, template creation is a simple process where a user can indicate data regions (area captured within the source document) and fields on the document. This template instructs Astera about how it should process a document.
The extraction template for our transcript will look like this:
Data Preview
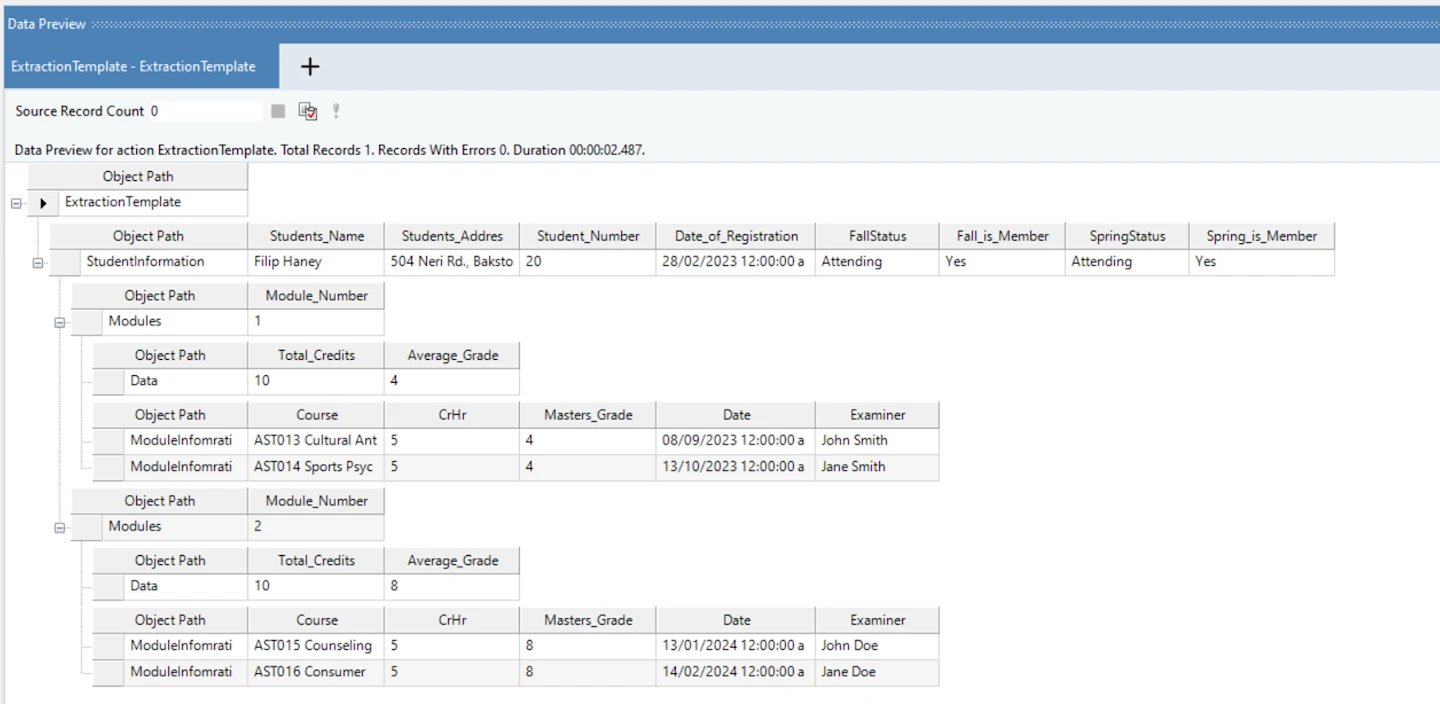
Astera’s ‘Preview Data’ feature allows users to preview the output of the extraction template and verify that it’s functioning correctly.
The data preview for the sample transcript will be as follows:
Exporting The Transcript
The Report Source object is using the transcript and the extraction template we designed to Once the extraction template is built and verified, we can run it and export the extracted data into a specified destination. In this use case, our destination is an Excel file. We are now working in a dataflow where we can use the external data in our data pipelines. We can process it further and load it into our desired destination.
For the sake of simplicity, we are writing our extracted data to Excel via the Excel Workbook Destination object.
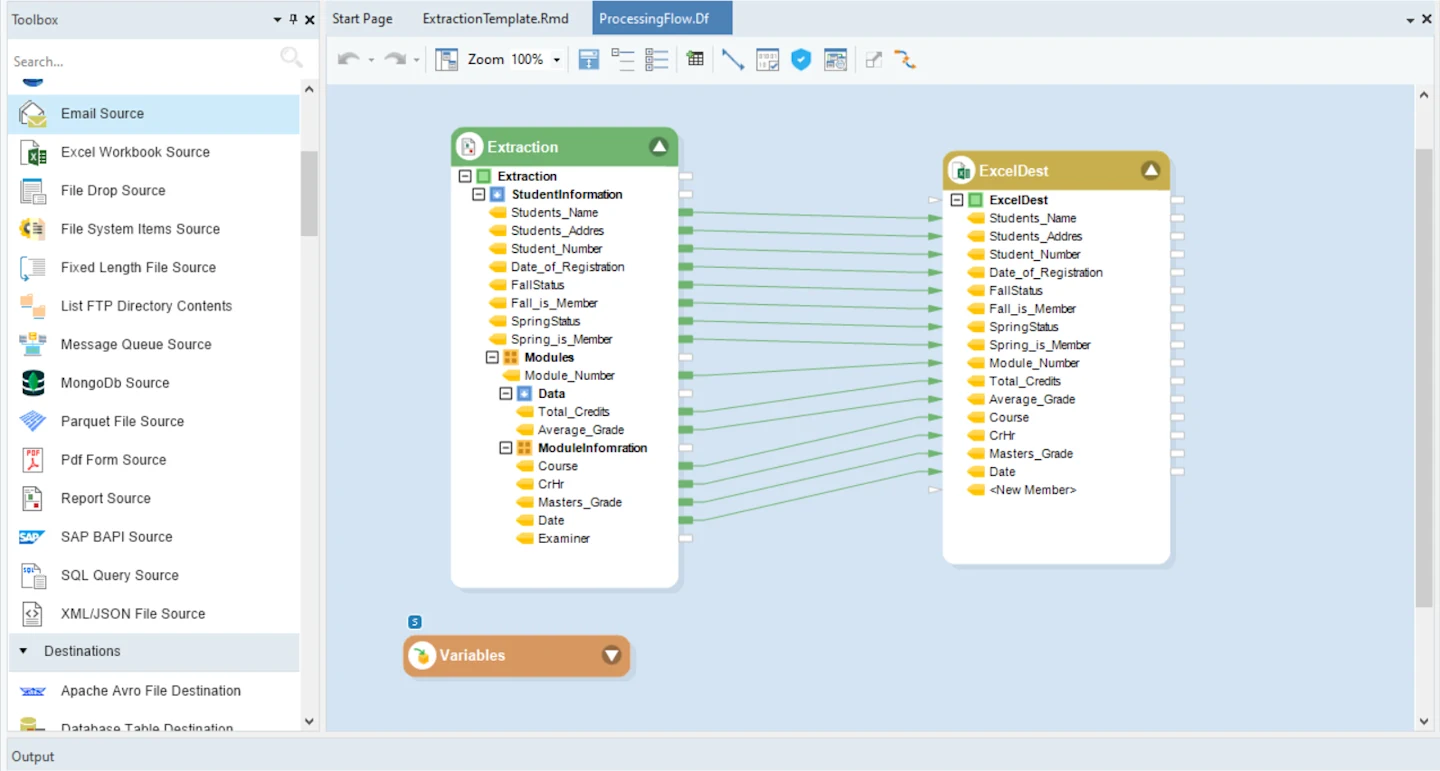
Now the destination is configured to append transcript records to the same Excel file.
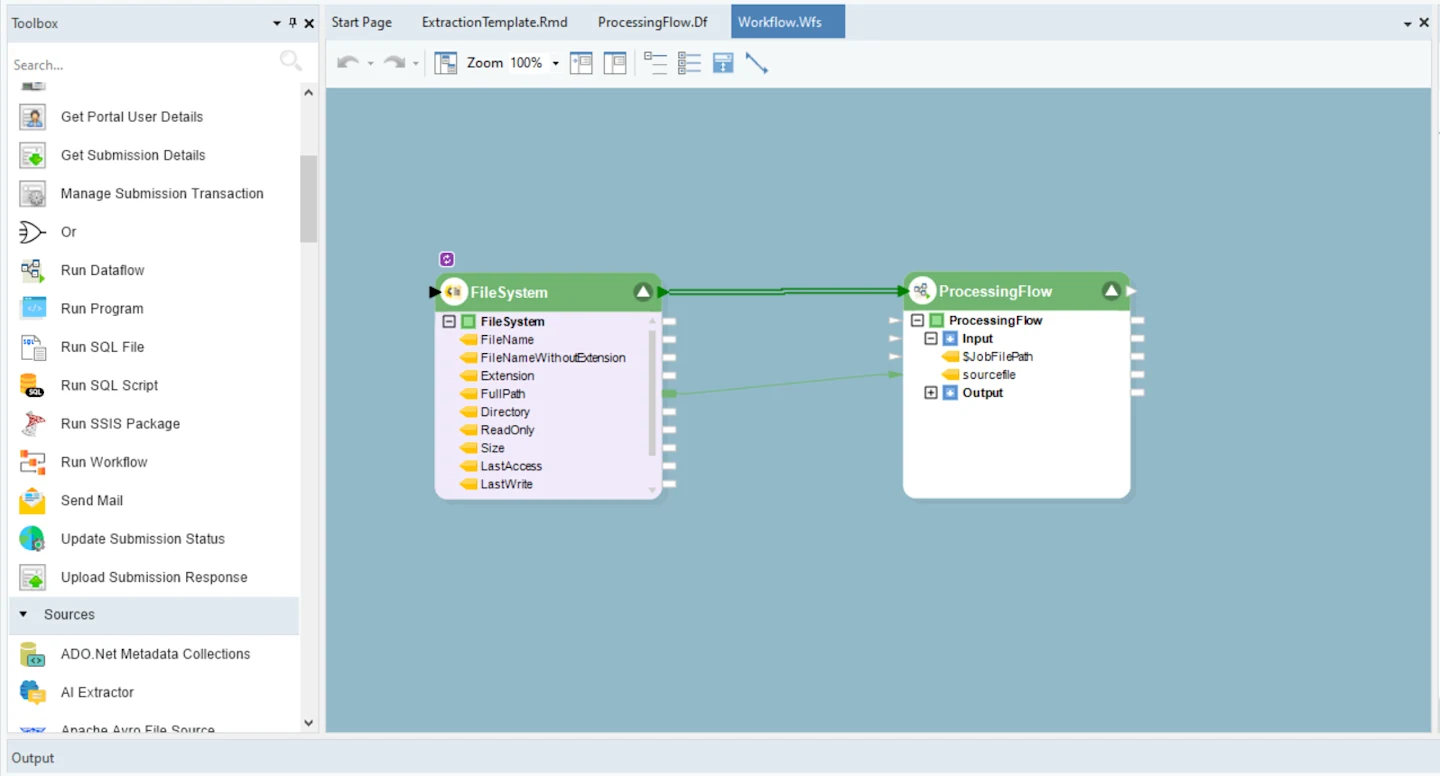
To process multiple transcripts and write them to our consolidated destination automatically, we have designed our workflow with the File System Item Source Object (to access all the files inside our transcripts folder) linked to the Run Dataflow object in a loop, processing each transcript through our designed flow and writing them to the Excel file.
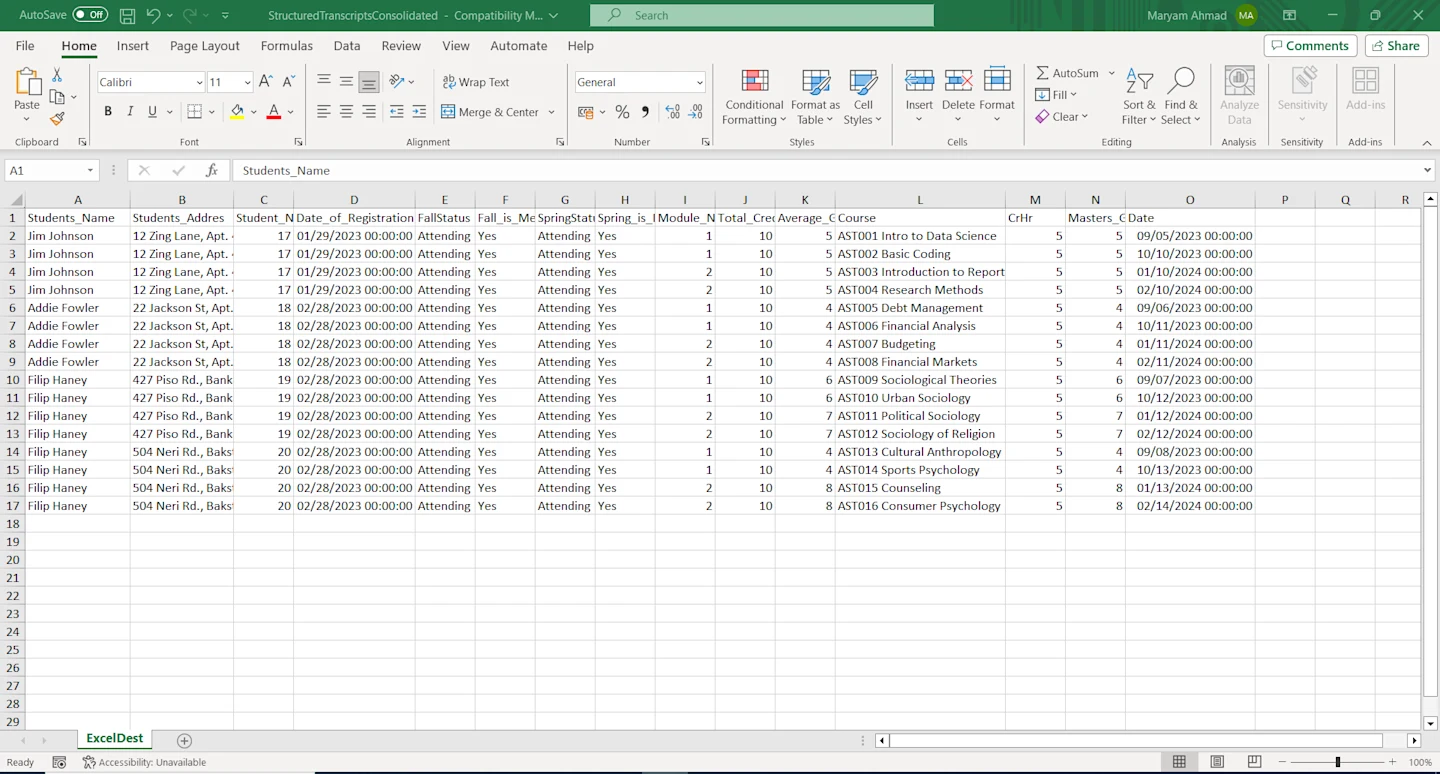
Multiple transcripts processed and exported to Excel will appear as follows. Note that Excel flattens hierarchical data so if, for example, a student has four course records, the exported data in Excel will show four separate entries for each course, and each entry will have the student’s name.
Processing The Data
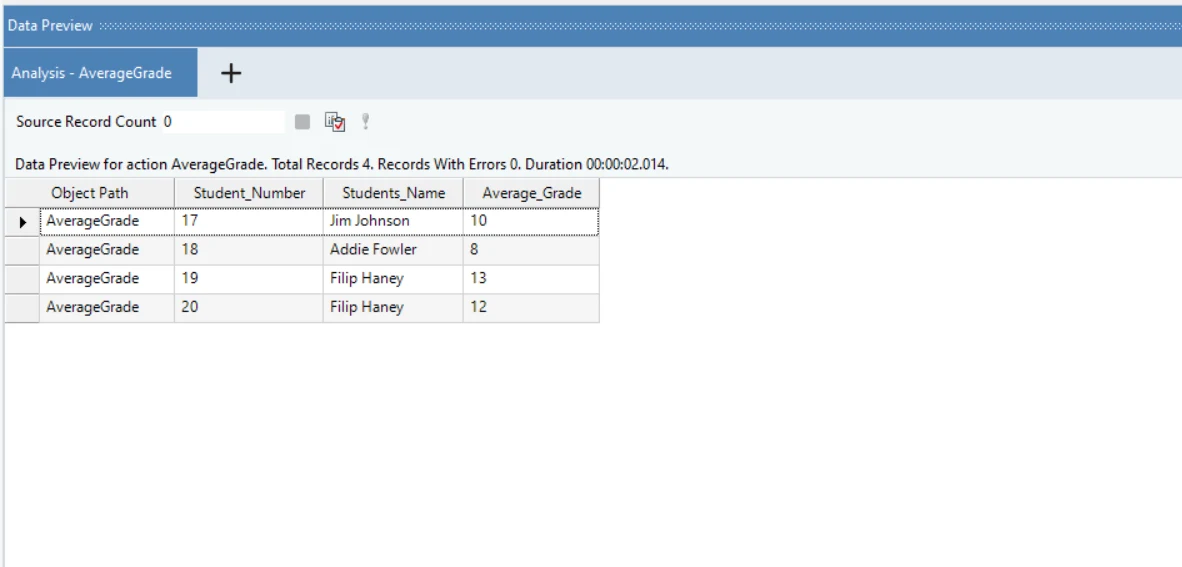
Data can be processed in different ways to generate new insights. Here, we are processing the consolidated transcripts data generated in the last step to view students’ average grades:
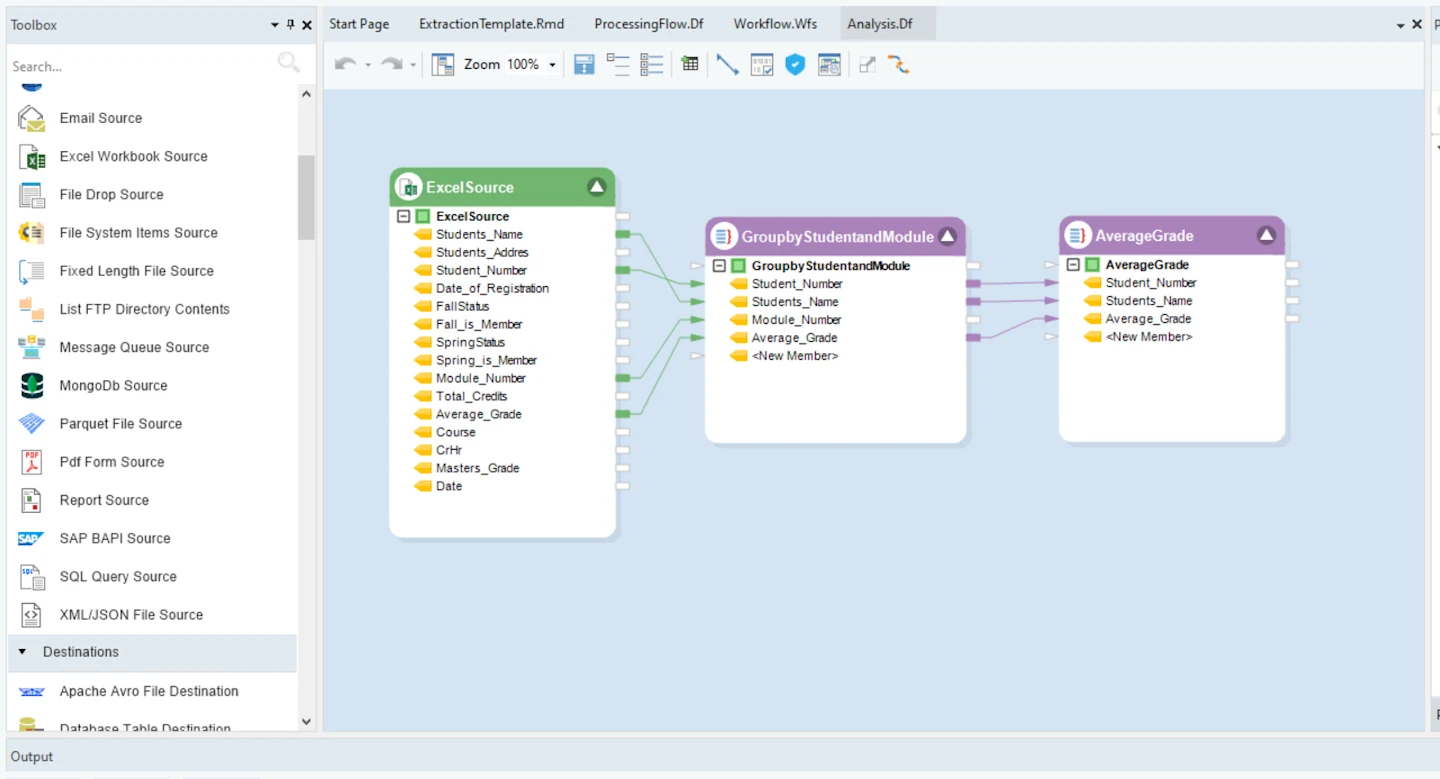
Previewing such a data pipeline will show us the average grades and make additional information — such as the highest-scoring student — easily visible.
Conclusion
AI is here to stay, and automated transcript processing is quickly becoming essential for every academic institution.
Educational institutions at every level can benefit tremendously from implementing AI-powered transcript processing into their workflows. Move to automated form processing with Astera and discover its benefits today.
Request a quote or start your free trial now.