

What is Change Data Capture (CDC)?
Change data capture (CDC) is a data integration technique that identifies inserts, updates, and deletes in a source database and delivers only those changes to target systems, such as a data warehouse, data lake, or application, in real time or near real time. Instead of reloading entire tables, CDC keeps downstream systems in sync with the source while putting minimal load on it.
Because a database is a large, constantly changing collection of records, it is difficult to track what has been added, modified, or deleted. As a data management technique, CDC solves this by watching the source for changes and recording them as they happen.
Real-time CDC is more efficient than traditional batch ETL (extract, transform, load), which is resource-intensive and time-consuming. For instance, the SQL Server database of an e-commerce website stores information about customers who place orders. Without CDC, updating that customer information downstream means extracting the entire dataset, processing it, and reloading it.
With SQL Server change data capture, the system identifies only the new or changed customer records and moves them in real time. This is why CDC is widely used in data warehouses, where current data is essential for analytics and reporting. It also improves reliability by keeping a constant flow of data between systems.
How Change Data Capture Works
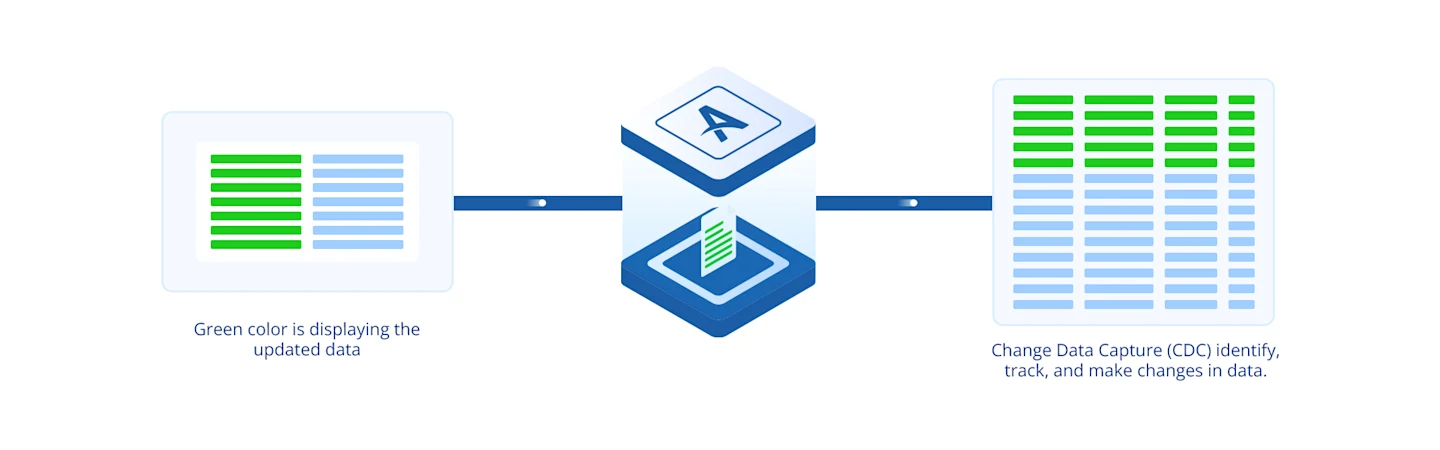
Below is a step-by-step explanation of how change data capture typically works.
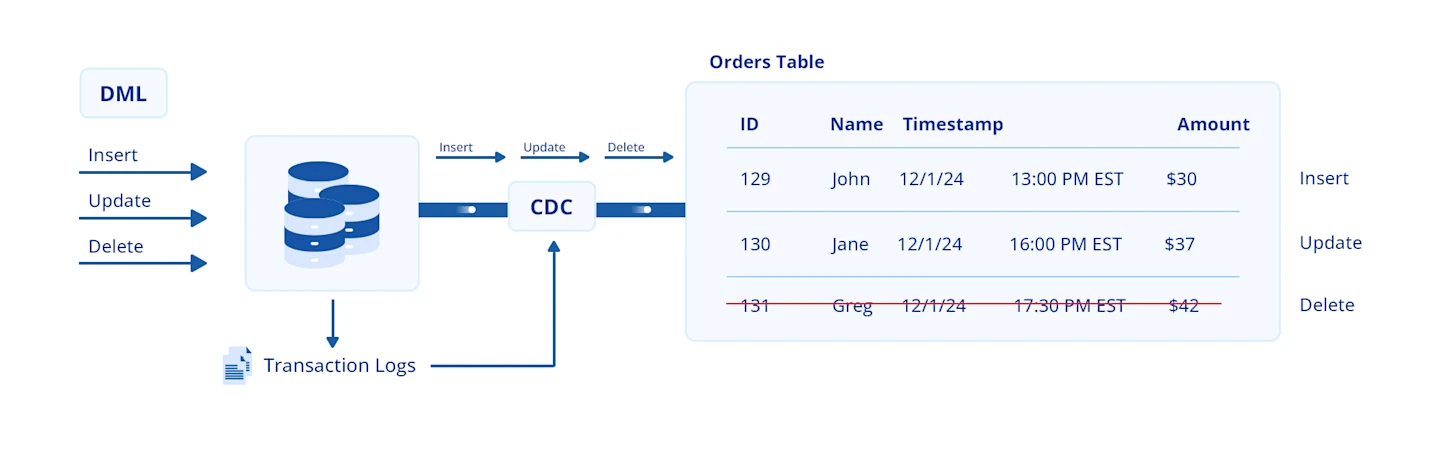
Change Identification: The CDC system is set to continuously scan the transaction log to find any changes, such as inserts, updates, or deletes. It looks for information related to what changed and which rows were affected.
Approach: Depending on their use case and requirements, organizations set up different change data capture approaches. Common methods include the log-based approach which involves monitoring the database transaction log to identify changes, and trigger-based CDC where certain triggers are used to capture changes.
Capture Relevant Information: Once a change occurs, the CDC system captures the relevant information from the transaction log. This will include the type of change (insert, update, delete), the timestamp (when the change occurred), and the affected rows.
Data Storage: The captured data is then stored in a separate repository, tables, or a dedicated CDC database. This is done to ensure the data can be easily analyzed without affecting the performance of the source database.
Delivery: After data storage, there may be a need to deliver this information to downstream systems. This could include analytics platforms, data warehouses, or other applications.
Ongoing monitoring and management of the CDC process is also essential in handling any errors that occur during change capture. Change data capture also maintains a history of changes over time, which is valuable for analytics and auditing purposes.
Why Change Data Capture Matters
Data Replication
In high-availability cases, maintaining consistent and updated data across different locations is important. This is particularly important in sectors like e-commerce and telecommunication, where uninterrupted access to up-to-date data is essential for customer service and compliance. In such scenarios, data replication is a key strategy to ensure redundant systems have synchronized data.
CDC operates in near real-time and plays its role in data replication by continuously identifying changes at the source system. This helps keep data constant and up to date at all locations.
Audit and Compliance
Organizations must comply with regulatory bodies that mandate them to maintain an audit trail of data changes. Non-compliance can lead to reputational damage and severe penalties. Change data capture is beneficial in this scenario as well. It provides a detailed record of the data’s additions, deletions, and modifications. This helps comply with regulations and serves as a mechanism to detect and rectify any unauthorized changes.
Cloud Migration
Cloud migration is challenging for most organizations as they have to move large volumes of data from on-premises environments to the cloud. This transition is often done to benefit from the cost-effectiveness, flexibility, and scalability that cloud platforms offer. However, it is challenging in terms of bandwidth, time, and resource utilization.
With CDC, you can track and replicate only the changes in data, reducing migration time and bandwidth requirements. This makes the move to cloud infrastructure smoother, whether you are migrating a data warehouse to the cloud or a single operational database.
Change Data Capture Methods
The right CDC method depends on your database, how fresh the data needs to be, and how much load the source system can handle. The three most common methods are timestamp-based, log-based, and trigger-based CDC.
Time-based Change Data Capture
When a row in a database table has a more recent timestamp than the last time data was captured, it is considered a change. The timestamp column is typically called ‘LAST_MODIFIED.’ This method is simple to implement, as you only need to keep track of when the most recent changes were extracted.
However, this method cannot track or identify deleted rows. The target systems must also go through each row to find the latest updates.
Log-based Change Data Capture
Most databases contain transaction logs, also called redo logs, that record all the changes made to the database (Insert, update, and delete). These logs prove useful during crashes for recovery purposes. The transaction logs can propagate changes to the target system without the need to scan operational tables. However, it leads to increased resource usage and storage overhead due to growing transaction logs. Still, log-based CDC is ideal for most occupied databases that cannot afford a lag.
Each database exposes its log differently: the transaction log in SQL Server, the binlog in MySQL, and the write-ahead log (WAL) in PostgreSQL. Tools such as Debezium read these logs and stream the changes to targets. For a hands-on example, see our guide to change data capture in PostgreSQL.
Trigger-based Change Data Capture
Each time data is inserted, updated, or deleted in a table, a corresponding trigger is activated to record the change in a separate table. One trigger per table is needed to capture every change. This approach creates a full version history, making the data easier to retrieve.
However, running triggers on operational tables adds overhead and can affect database performance, as every update requires multiple writes.
Comparing CDC Methods
Here is how the three methods compare at a glance:
Method | How changes are detected | Captures deletes? | Impact on source | Typical latency | Best for |
Log-based | Reads the database transaction (redo) log | Yes | Low | Seconds (real time) | High-volume production databases |
Trigger-based | Triggers write each change to a separate table | Yes | High (extra writes on every transaction) | Near real time | Databases without log access, or when full change history is needed |
Timestamp-based | Queries rows where LAST_MODIFIED is newer than the last run | No | Medium (repeated queries) | Minutes (set by the polling interval) | Simple tables with few changes |
Push vs. Pull Delivery
Whichever method captures the changes, they still need to reach the target system. There are two ways to deliver them.
In the push approach, all processes occur on the source dataset that trigger notifications for changes (insertions, edits, deletions) in real time. The source system pushes the information about the change to the target system. Note that the change in data won’t be noticed if the target system is offline.
In the pull method, the CDC system pulls changes from the source system at scheduled intervals. This puts less load on the source database. Like the push approach, the pull method needs an intermediary, such as a message broker like Apache Kafka, to hold changes while a target system is offline.
Experience Effortless Data Integration Using Change Data Capture with Astera Centerprise
Stay ahead of the curve with real-time data updates. Astera Centerprise ensures that your data is always current, providing a competitive edge.

Change Data Capture Examples and Use Cases
Change data capture is used wherever a system needs to react to data changes as they happen. Common examples include:
Real-time data warehouse loading: CDC streams only new and changed rows into the warehouse or lakehouse, so dashboards reflect the latest data without nightly full reloads. Learn more about incremental data warehouse loading with CDC.
Zero-downtime database migration: During a migration, CDC keeps the old and new databases in sync, so applications can switch over without a long outage.
Fraud detection and operational analytics: A bank can stream card transactions to a fraud detection model the moment they are written, instead of hours later.
Cache and search index updates: An e-commerce site can update product availability in its search index or cache as soon as inventory changes in the order database.
Event-driven microservices: Each service can subscribe to the changes it cares about, such as a new order, without querying another service’s database directly.
Change Data Capture in ETL
ETL is a data integration process that brings updated data from a source system to a target database. The data extraction can be done through full data queries or through change data capture. CDC is therefore best seen as a smarter way to extract data within ETL, not a replacement for it. For other approaches, see our overview of data integration techniques.
Here’s what CDC looks like through different stages of ETL:
Extract: In the past, data extraction involved large batches, causing delays in reflecting source system updates in the target database. Now, with change data capture, data is extracted in real time, capturing only the changes as they occur. This targeted approach significantly reduces the volume of data processed, optimizing the overall ETL process.
Transform: Transformation is the process of converting a dataset’s structure and format to match the target database. Since the traditional methods involved bulk extraction and transformation, this would take a lot of time. However, in CDC, where transformation remains a key step, data is loaded efficiently and transformed directly into the target repository. This makes CDC approach well-justified with the increasing database sizes.
Load: This refers to the actual placement of data in the target system. Technically, the transformation and loading occur simultaneously with CDC, making it a more efficient procedure.
CDC vs. Traditional Batch ETL
Aspect | Traditional batch ETL | ETL with change data capture |
Data moved | Full tables or large batches | Only rows that changed |
Data freshness | Hours to days old | Seconds to minutes old |
Load on source | High during extraction windows | Low, especially with log-based CDC |
Deleted records | Found only by full reloads or comparisons | Captured as they happen |
Best for | Historical loads and rarely changing data | Continuous sync and real-time analytics |
Overcoming Common Change Data Capture Challenges
Bulk Data Management
Handling large volumes of changes at once can strain CDC pipelines and reduce their efficiency. For example, on a cloud collaboration platform where users continuously create, edit, and share files, CDC captures document changes smoothly under normal load. During peak periods, however, thousands of simultaneous edits can send a surge of changes through the pipeline.
To address the challenge, consider implementing efficient tools such as distributed processing frameworks, and optimizing the deployment strategy like scaling resources dynamically based on usage patterns. Moreover, enhancing the CDC pipeline and using advanced data processing techniques can help manage simultaneous file edits more effectively.
Schema Changes
Schema changes can disrupt data mapping and synchronization between source and target systems. These changes can complicate CDC, as it needs to adapt to evolving database structures. CDC adaptation can help cater to these changes. Advanced CDC solutions often employ metadata and intelligent algorithms to adjust to schema changes.
Data Integrity
Implementing CDC can make it difficult to maintain data consistency and integrity, especially during complex transformations. The risk of errors may arise due to concurrent changes and potential disruptions due to data mapping.
This challenge can be easily overcome by validation checks, strong error handling, and reconciliation mechanisms. Moreover, versioning and rollback mechanisms can provide traceability and quick correction, hence maintaining the integrity of transformed data.
Resource Consumption
CDC can consume substantial system resources, leading to performance issues for concurrent applications. This is mainly due to the demand for disk I/O, CPU, and memory during data extraction, transformation, and loading.
A series of optimization strategies can be implemented to address this challenge. For instance, throttling mechanisms can be used to control the rate of data processing. Moreover, fine-tuning parameters such as batch size and parallelism can be employed to align with the system’s capacity.
Benefits of Change Data Capture
Large databases need an efficient data integration system that operates in real time. Here is what change data capture offers:
Consistency Across On-Premises and Cloud Systems
Companies are increasingly moving to the cloud so they can focus on innovation instead of maintaining infrastructure. According to Flexera’s 2025 State of the Cloud Report, 55% of workloads already run in the public cloud, with another 6% expected to move within 12 months. CDC keeps on-premises and cloud databases consistent during and after that move, preventing discrepancies between them.
Swift Response
CDC has an edge over traditional methods that update entire datasets. Batch pipelines leave analytics hours or days behind, and stale data is of little use when dealing with real-time threats. Demand for fresher data is growing: in Confluent’s 2025 Data Streaming Report, 86% of 4,175 IT leaders ranked data streaming as a strategic priority, and 90% planned to increase their investment in it.
CDC is helpful in capturing and analyzing data changes in real–time. With CDC, a cybersecurity firm can detect and respond to security breaches. This enables swift action to prevent the compromise of sensitive information before significant damage occurs.
Microservices Architecture
Data needs to be transferred from source datasets to multiple destination systems. It becomes easier using CDC as it helps maintain synchronization between source and target datasets during the process. Taking the real-time data transfer approach, it’s now more convenient to synchronize multiple data systems no matter where they are.
Less Load on Operational Databases and Faster Processing
Operational databases already carry the load of day-to-day transactions. Traditional synchronization adds to that strain by repeatedly querying or copying whole tables. CDC captures and transmits only the changes made since the last sync, which keeps the source responsive and gets data to analytics and applications faster.
Maintaining Competitive Advantage
Many organizations still rely on nightly batch jobs to refresh their analytics. Replacing them with change data capture gives teams current data for every decision, and its value grows as data spreads across more systems and clouds.
Furthermore, CDC empowers business agility by letting enterprises stay updated with their data as it facilitates replication across various cloud environments. This benefits those companies dealing with diverse cloud solutions, whether a combination of public, private, or hybrid clouds.
Change Data Capture with Astera Data Pipeline
To ensure the business thrives for the years to come, decisions should be based on real-time data. And to synchronize all the databases within an organization for a coherent approach, change data capture is one of the potential solutions as it minimizes disruption during data transfer and reduces costs.
Astera Data Pipeline simplifies CDC by enabling seamless tracking, extraction, and integration of modified data across systems. With built-in support for real-time and batch processing, it efficiently captures inserts, updates, and deletes, ensuring your data remains up to date without requiring full reloads. AI-driven semantic mapping and automatic API creation further streamline data movement, allowing businesses to synchronize changes across databases, cloud platforms, and applications effortlessly.
Whether you’re maintaining a live data warehouse, enabling real-time analytics, or ensuring regulatory compliance, Astera Data Pipeline’s unified approach to CDC ensures accuracy, speed, and minimal operational overhead. The tool supports various change data capture methods for different databases, including time-based, log-based, and trigger-based mechanisms. Learn more about Astera’s change data capture solution.
Experience the advantages of change data capture with a 14-day free trial of Astera Data Pipeline. Sign up today to explore the functionality and benefits firsthand.