

Data wrangling is the process of taking raw, messy, or inconsistent data and turning it into a clean, structured format that's ready for analysis.
Real-world data rarely arrives ready to use. It comes from different sources, in different formats, with missing values, duplicates, and inconsistencies that can derail analysis and decision-making if left unaddressed.
Data wrangling tools automate this transformation — structuring, cleansing, and enriching data according to what the end system or analysis requires, so teams spend less time fixing data and more time using it.
But what is data wrangling, and why is it so important? Read this article to find out.
What is Data Wrangling?
Data wrangling involves transforming and structuring raw data into a desired format to enhance data quality and usability for analytics or machine learning purposes. It’s also known as data munging. Data wrangling involves mapping data fields from source to destination, for example, targeting a field, row, or column in a dataset and implementing an action like joining, parsing, cleaning, consolidating, or filtering to produce the required output.
Key components of data wrangling include:
Transformation: Converting data from one format to another to meet analysis requirements.
Cleansing: Removing inconsistencies, errors, and outliers to ensure data accuracy.
Enrichment: Enhancing data by adding relevant information or combining it with other datasets.
Through data wrangling, the analyzed data becomes more accurate and meaningful, leading to improved solutions, decisions, and outcomes.
As organizations deal with larger volumes of diverse and unstructured data from multiple sources, the process of preparing data for analysis can be time-consuming and costly.
Self-service approaches and analytics automation can expedite and enhance the accuracy of data wrangling processes, reducing errors introduced by manual methods like Excel.
After wrangling, you can use the data to process it further for business intelligence (BI), reporting, or improving business processes. Therefore, the process ensures the data is ready for automation and further analysis.
Data Wrangling vs. Data Cleaning
Data wrangling and data cleaning are often used interchangeably, but they aren't the same process. Data cleaning is a narrower, corrective step — it deals with what's already wrong in a dataset. Data wrangling is the broader pipeline that takes raw data from its source to an analysis-ready state, and cleaning is just one stage inside it.
What data cleaning actually does. Data cleaning targets specific defects in a dataset: removing exact and fuzzy duplicates, standardizing inconsistent formatting (date formats, capitalization, units of measurement), handling missing values through deletion or imputation, detecting and addressing outliers, and resolving referential integrity issues like orphaned foreign keys. It operates on data that's already been extracted and roughly structured — cleaning doesn't pull data from a source system or reshape its schema.
Where data wrangling picks up more. Data wrangling includes cleaning, but also covers steps cleaning doesn't touch: extracting data from disparate source systems (APIs, flat files, databases), restructuring it into a target schema (pivoting, joining, normalizing or denormalizing tables), enriching it with context from other datasets (geocoding an address, appending a customer segment), and validating it against business rules before it's considered ready for use. In a typical pipeline, cleaning happens after extraction and before or alongside transformation and enrichment — it's a checkpoint within wrangling, not a separate track.
Data Cleaning | Data Wrangling | |
Scope | Fixing defects in existing data | End-to-end: extract, structure, clean, enrich, validate |
Typical operations | Deduplication, standardization, missing-value handling, outlier detection | Schema mapping, joins/merges, type conversion, enrichment, validation rules |
Input | Data that's already been extracted | Raw data straight from the source system |
Output | A corrected version of the same dataset | An analysis-ready dataset, potentially reshaped and combined with other sources |
In short: every data wrangling project involves cleaning, but not every cleaning task is part of a larger wrangling effort.
Better Analytics Starts With Better Data
Astera cleans and delivers analysis-ready data to your BI platform of choice, so your team spends less time on prep.

Data Wrangling vs. Data Mining
Some people struggle to understand the difference between data munging and data mining. Data mining techniques involve finding patterns and relationships hidden in large data sets. It helps businesses to decipher meaningful patterns in their data, whether it is open-source data or not.
On the other hand, it is a superset of data mining and requires multiple other decision-making processes, such as data cleaning, transforming, integrating, etc. In this regard, wrangled data is important for accurate reporting and business intelligence insights.
Why Do You Need It?
Do you know that professionals spend almost 73% of their time wrangling data? This means it’s an indispensable aspect of data processing. It helps business users make concrete, timely decisions by cleaning and structuring raw data into the required format. Data wrangling is becoming a common practice among top organizations as the data becomes more unstructured and diverse.
Accurately handled data ensures that quality data is entered into analytics or downstream processes for consolidation and collaboration. It is essential to optimize the data-to-insight journey and support accurate decision-making.
Data wrangling can be arranged into a consistent and repeatable procedure using data integration tools with automation capabilities that clean and convert data sources into a reused format per the end requirements. After reverting data to a standard format, you can perform crucial cross-data set analytics. Moreover, data wrangling with Python is typical as Python employs different methods to wrangle the data stored in different data sets.
Steps to Perform Data Wrangling
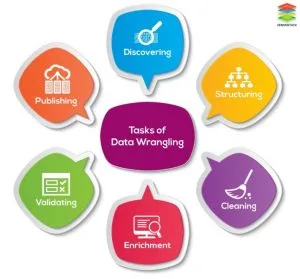
Like most data analytics processes, it is an iterative process in which you must perform the five steps recurrently to get your desired results. These five steps are as follows:
· Understanding Data
The first step is to understand the data in great depth. Before applying procedures to clean it, you must have a clear idea of what the data is about. This will help you find the best approach for productive analytic explorations. For instance, if you have a customer dataset and learn that most of your customers are from one part of the country, you’ll keep that in mind before progressing.
· Structuring
In most cases, you’ll have raw data in a disorganized manner. There won’t be any structure to it. In the second step, you have to restructure the data type for easy accessibility, which might mean splitting one column or row into two or vice versa – whatever is needed for better analysis.
· Cleansing
Almost every dataset includes some outliers that can skew the outcomes of the analysis. You’ll have to clean the data for optimum results. In the third step, you have to clean the data exhaustively for superior analysis. You’ll have to change null values, remove duplicates and special characters, and standardize the formatting to improve the consistency of the data. For example, you may replace the many different ways that a state is recorded (such as CA, Cal, and Calif) with a single standard format.
· Enriching
After the third step, you must enrich your data, which means taking stock of what’s in the dataset and strategizing how to improve it. For example, a car insurance company might want to know crime rates in the neighborhoods of its users to estimate risk better.
· Validating
Validation rules denote some repetitive programming steps that are used to authenticate the reliability, quality, and safety of the data you have. For instance, you’ll have to determine whether the fields in the dataset are precise by cross-checking data or observing whether the attributes are normally distributed.
Data Wrangling Examples
The steps of data wrangling look different depending on the source and destination, but the underlying pattern — extract, structure, clean, enrich, validate — shows up across industries. A few concrete examples, with the techniques involved:
Merging regional sales spreadsheets. A retail company pulls weekly sales exports from five regional teams. Each file uses different column names ("Rev" vs. "Revenue" vs. "Total_Sales"), different date formats (MM/DD/YYYY vs. DD-MM-YY), and different currency symbols.
Wrangling this data means mapping each file's columns to a single canonical schema, parsing and standardizing all date fields to ISO 8601, converting currency values to a base currency using exchange-rate lookups, and concatenating the results into one table validated against expected row counts per region before it's loaded into a reporting warehouse.
Preparing customer data for a CRM migration. Before moving customer records into a new CRM, a team extracts records from the legacy system, then applies fuzzy matching (such as Levenshtein distance on name and address fields) to identify and merge duplicate contacts that don't match exactly.
Phone numbers are normalized to E.164 format, addresses are standardized against a postal reference dataset, and fields missing from the source — like a lead source or account owner — are backfilled from a secondary export before loading.
Cleaning survey response data. A research team exports raw survey responses where open-text answers need to be mapped into a fixed set of categories (often via keyword matching or a lookup table built from a first coding pass), Likert-scale responses are checked for straight-lining (identical answers across every question, a common sign of low-quality responses) and flagged, incomplete responses below a completion threshold are excluded, and numeric responses are checked against expected ranges to catch outliers or data-entry errors.
Structuring log files for analysis. Raw server logs arrive as semi-structured text, one line per event. Wrangling this data means parsing each line with a regular expression to extract structured fields — timestamp, IP address, HTTP method, status code, response time — casting each field to its correct type (timestamps to datetime, status codes to integers), filtering out noise like health-check pings, and loading the structured output into a table that can be queried and visualized instead of read line by line.
Automate All Five Steps in One Platform
Stop writing custom scripts for every transformation. Use natural language to ingest, clean, transform, engineer, and validate—all in a unified workspace with instant preview.
Common Use-Cases
Two of the most common use cases include:
Fraud Detection
Using a data wrangling tool, a business can perform the following:
Distinguish corporate fraud by identifying unusual behavior by examining intricate information like multi-party and multi-layered emails or web chats.
Support data security by allowing non-technical operators to examine and wrangle data quickly to keep pace with billions of daily security tasks.
Ensure precise and repeatable modeling outcomes by standardizing and quantifying structured and unstructured sets of data.
Enhance compliance by ensuring your business complies with industry and government standards by following security protocols during integration.
Customer Behavior Analysis
A data munging tool can help your business processes get precise insights quickly via customer behavior analysis. It empowers the marketing team to take business decisions into their hands and make the best of them. You can use data wrangling tools to:
Decrease the time spent on data preparation for analysis
Quickly understand the business value of your data
Allow your analytics team to utilize the customer behavior data directly
Empower data scientists to find out data trends via data discovery and visual profiling
Expedite Data Integration with an Automated ETL Tool
View DemoClean your Data Using an Automated Data Wrangling Tool
Data wrangling is an essential part of the process for a business that wants to enjoy the finest and result-driven BI and analytics. You can use automated tools for data wrangling, such as Astera Centerprise. The software extracts data and transforms, cleans, and structures it into the business-required format to be consumed for analytics and BI. Wrangled data provides accurate results that help companies strategize accordingly.
Try Astera Centerprise firsthand, and see how it can help you simplify data wrangling.