

A data mart is a focused, subject-specific subset of a data warehouse, built to serve the reporting and analysis needs of a single team or department — sales, finance, or HR, for example — rather than the entire organization. Because it draws from a smaller, more targeted set of data than a full warehouse, a data mart is faster to query, cheaper to implement, and easier to govern.
A well-designed data mart architecture reduces the risk of data loss and cuts implementation time and cost, precisely because it focuses on a relevant subset of data rather than an entire enterprise warehouse.
This guide covers what a data mart is, its architecture and types, and the best practices for designing one that scales.
Build Your Data Mart From Scratch
Find out How
Definition of Data Mart
Data mart is defined as a shortened or condensed version of an enterprise data warehouse. It draws information from a smaller number of resources as compared to a data warehouse. Data mart architecture is catered towards the needs of very specific business units, functions, or departments.
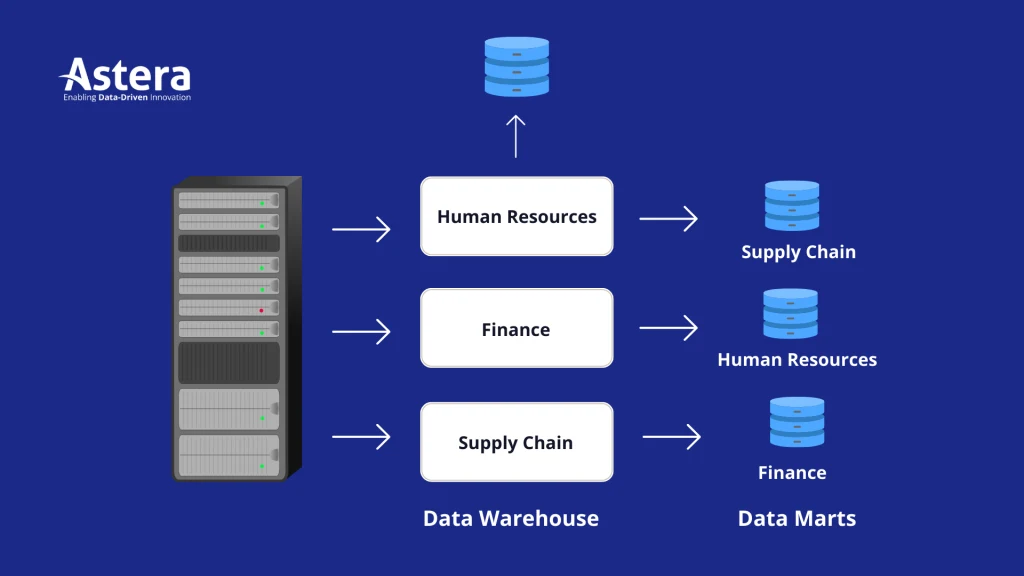
Data Marts Explained
Why Does A Business Need Data Mart?
There are multiple benefits of developing an independent data mart architecture for business users, such as:
By reducing the volume of data, a data mart helps to improve user response time and offers quick access to frequently used data.
It is easy to implement with much less cost, as compared to implementing a full data warehouse.
It is scalable and agile, which comes in handy when changing models.
Data is segregated in data mart which allows more control over the data rights i.e. who can view and modify the data.
Data can be stored and organized on distinct hardware or software platforms.
Types of Data Marts
Data marts are typically built using one of three architectural approaches, and the choice affects everything from implementation speed to long-term data governance.
1. Dependent Data Marts
Dependent data marts draw their data from an existing centralized data warehouse rather than pulling directly from source systems. Data flows from operational systems into the warehouse first, where it's cleaned, integrated, and conformed to a consistent schema, and the data mart then extracts a relevant subset from that already-governed layer.
Because it inherits the warehouse's data model and quality controls, a dependent data mart is the most consistent and easiest to govern of the three approaches. If the finance and sales data marts both pull "customer" data from the same warehouse, they're guaranteed to use the same definition of a customer. The trade-off is that a dependent data mart can't exist without an underlying warehouse already in place, which means more upfront infrastructure investment before any individual mart can be built.
2. Independent Data Marts
Independent data marts are built directly from one or more source systems, without a centralized warehouse as an intermediary step. This makes them the fastest option to stand up. A team can go from source data to a working data mart in days rather than months, since there's no need to wait for enterprise-wide warehouse infrastructure.
The risk is consistency: without a shared, governed layer in between, two independent data marts built by different teams can define the same metric (like "revenue" or "active customer") differently, leading to numbers that don't reconcile when compared across departments. Independent data marts are often the starting point for organizations that haven't yet built a warehouse, sometimes maturing into dependent marts once one is established.
3. Hybrid Data Marts
Hybrid data marts combine data drawn from a centralized warehouse with additional data pulled directly from other source systems the warehouse doesn't yet cover. This offers a middle ground: it retains much of the governance and consistency benefit of a dependent mart for the data that does flow through the warehouse, while still giving teams the flexibility to incorporate niche or fast-moving data sources without waiting for formal warehouse integration.
Hybrid marts are common in organizations mid-way through a warehouse migration, or in teams that need to combine core enterprise metrics with a specialized external data source, like third-party market data or a new SaaS tool that isn't yet warehouse-integrated.
Dependent | Independent | Hybrid | |
Data source | Central data warehouse | Source systems directly | Both warehouse and source systems |
Setup speed | Slower — requires a warehouse | Fastest | Moderate |
Consistency | Highest | Lowest | Medium-high |
Best for | Organizations with an existing warehouse | Fast-moving teams without a warehouse yet | Mixing governed and specialized data |
Best Practices for Data Mart Architecture Design
To ensure the efficiency and scalability of your enterprise data mart architecture, follow these data warehouse design tips.
1. Define the Scope of Data Mart
Before jumping to the implementation phase of your enterprise data mart model, it’s essential to have a fool-proof plan that takes into consideration all the business needs and priorities of all team members and end-users.
Start by outlining the scope of the project, highlighting all risks and limitations. It’ll help set the right expectations and estimate expenses.
You may have to adjust the requirements with respect to the resources (like human, technical, and financial resources) to keep up with the planned completion date.
In the light of this scope, develop the list of main deliverables and allocate duties to your team.
2. Pay Attention to the Logical Data Mart Model
A logical data mart model is a theoretical, intangible design that organizes data in terms of logical relations known as entities and attributes. An entity is a data item, whereas an attribute helps define the exclusivity of the entity.
When laying out the data mart architecture, focus on your business needs. Map source data to subject-oriented information in the destination data mart schema. The source data model and end-user requirements are the essential elements used to design a data mart schema.
You may have to modify the physical implementation of the logical data model based on the system parameters, such as the computer size, number of operators, disk storage, network type, and software.
Streamline Your Data Mart Management
Free Trial3. Identify Relevant Data
Generally, data elements are identified based on the business requirements. However, you may often have to look beyond the end-user requests and expect upcoming requirements.
A good tip is to begin with the business factors relevant to your subject area and critical to your department. For instance, if you’re designing a data mart model for your sales and marketing department, key factors might be client, location, product, sales, and promotions. Also, consider if you’re interested in monthly, daily, or weekly records.
Next, generate a list of critical data fields based on the needs put forward by the data mart operators. For instance, some fields of interest in the marketing data mart could be product names, promotion characteristics, areas, and countries.
You should also divide the data into numeric metrics (called facts) and descriptive records (called dimensions).
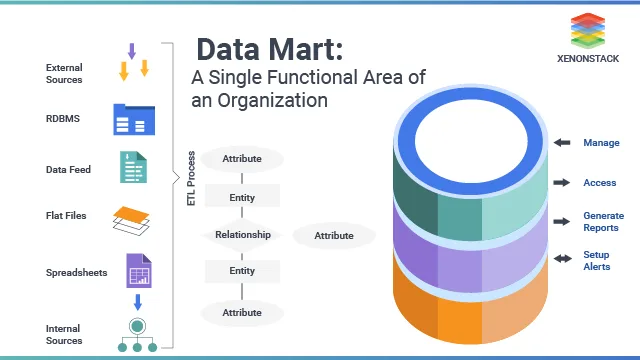
Source: xenonstack
4. Narrow Down the Data Sources
Once you’ve listed all dimensions and facts that will make up the data mart model, the next step is to identify the sources that will feed the repository. These sources can include databases, Excel files, delimited files, etc.
Next, proceed to map dimensions to lookup tables in your operational system whereas, and facts can be mapped to transaction tables.
You may also find out that some of the required data cannot be mapped. This typically occurs when fields in the source system aren’t consistent with the required data groups in the data mart.
For instance, in a telecom corporation, phone calls can be grouped by area code, but the data mart requires data in terms of postal code. Now it’s difficult to map these dimensions, as one area code comprises of many postal codes, and a postal code can include several area codes. In this situation, translating data into a common system format could involve costly processing.
5. Design the Star Schema
When creating a star schema, it’s essential to describe the relationship between the fact and dimension tables. This is done using keys that include single or multiple columns, making the row within a table exclusive. A primary key that includes several columns is known as a composite or concatenated key.
To link the facts and the dimensions, it’s good to use surrogate keys instead of the primary key of the actual source table. It allows the data mart manager to control the keys within the data mart environment, even if the keys change in the operational system.
A surrogate key is a system-created series of integers that can be included in the dimension table along with the primary key. It offers more benefits as compared to a primary key because the latter is often a lengthy string of characters. Whereas, a primary key includes integers, so it improves the query response time.
Unlock the automated route to designing your data mart
Download WhitepaperData Marts vs. Data Warehouse
A data mart and a data warehouse both store data for analysis, but they differ in scope, scale, and how they're typically built.
Architecturally, a data warehouse is usually modeled with a more normalized or lightly denormalized schema — often closer to third normal form or a snowflake schema — designed to serve as a single, comprehensive source of truth across the organization.
A data mart is typically modeled with a star schema instead: a central fact table holding measurable metrics, surrounded by denormalized dimension tables holding descriptive attributes, optimized specifically for fast, simple queries within one business area rather than broad flexibility across the whole enterprise.
This difference in schema design is also why data marts generally deliver faster query performance for their specific use case — fewer joins, a smaller dataset, and a schema tuned to the exact questions one team asks most often.
Data Mart | Data Warehouse | |
Scope | Single team or department | Entire organization |
Size | Smaller, focused subset | Large, comprehensive |
Schema design | Star schema — optimized for fast, simple queries | Normalized or snowflake schema — optimized for broad flexibility |
Query performance | Faster for its specific use case | Slower for narrow queries, built for breadth |
Setup time | Faster — days to weeks | Slower — weeks to months |
Users | A specific business unit | Multiple departments and analysts |
Best for | Fast, focused reporting needs | Enterprise-wide analytics and a single source of truth |
One Last Thought
Over time, the data volume of your independent data mart is likely to increase. Thus, it’s essential to consider the factor of scalability when physically implementing your logical data mart model. To cater the scalability requirements, consider minimizing the restrictions of factors like hardware size, software capacity, and system bandwidths.
Designing a data mart architecture is a complex process that involves several time-consuming steps and at times, substantial costs. By following the five best practices mentioned in this article, you can reduce the chances of errors and speed up the designing process.