

AI data preparation is the process of collecting, cleaning, transforming, and validating raw data so that machine learning and AI models can learn from it accurately. It usually takes more time than any other stage of an AI project, and it has more influence on results than the choice of algorithm.
Most of that work doesn't need a data scientist. The people who know the data best, such as analysts, operations, finance, and marketing teams, are often the best placed to prepare it, as long as they have the right tools. This guide explains what AI-ready data looks like, walks through the five steps, flags the mistakes that quietly ruin models, and shows how to do the work in Astera Dataprep without writing code.
Why Data Preparation for AI Matters
Most AI projects that stall do so because of the data, not the model. Gartner found that 63% of organizations either lack or are unsure they have the right data management practices for AI. It predicted that organizations would abandon 60% of AI projects not supported by AI-ready data through 2026.
The upside of fixing data is just as large. Andrew Ng, founder of Google Brain and DeepLearning.AI, calls the approach data-centric AI: "systematically engineering the data used to build an AI system." On a steel-inspection project, two months of model tuning left accuracy at 76.2%. Two weeks spent improving the data raised it to 93.1%.
In practice, preparation gets stuck in three places:
Manual work doesn't scale. Spreadsheet fixes and one-off scripts have to be redone every time new data arrives.
Formats don't match. The CRM, the billing system, and the support desk each record dates, IDs, and categories their own way.
Data sits in silos. The fields a model needs are spread across departments, and each team waits on another to hand them over.
What Is AI Data Preparation?
AI data preparation turns operational data into the precise inputs a model needs. It builds on the same skills as preparing data for analysis, but with three important differences:
Models need signals, not just records. A dashboard can show a customer's order history. A model needs that history turned into measures such as "orders in the last 90 days" or "days since last purchase."
Small inconsistencies become big errors. A person reading a report knows "NY" and "New York" are the same. A model treats them as two different places.
The work repeats. Models are retrained as new data arrives, so preparation has to be repeatable, not a one-time cleanup.
For the fundamentals, see our complete guide to data preparation.
What Does AI-Ready Data Look Like?
AI-ready data is data a model can learn from without inheriting its errors or blind spots. Before you hand a dataset to a data science team or an AutoML tool, check that it is:
Quality | What it means in practice |
Complete | Missing values are handled on purpose, not left blank or dropped at random |
Consistent | One format per field: dates, currencies, units, IDs, and category names |
Accurate | Duplicates, typos, and impossible values are fixed or removed |
Representative | Every customer segment, region, or product line the model will serve is included |
Correctly labeled | The outcome you want to predict (churned, fraudulent, defective) is recorded accurately |
Governed | Sensitive fields are masked and you can trace where each record came from |
Fresh | The data is refreshed as often as the business changes |
Labels deserve special attention. MIT and Cleanlab researchers found an average of at least 3.3% label errors across 10 widely used benchmark datasets, and fixing them changed which model performed best. If benchmark datasets built by researchers contain errors, internal business data almost certainly does too.
Why Data Quality Defines AI Success
A model is only as good as the data it learns from. Train a fraud detection model on transactions where customer IDs occasionally swap, dates use mixed formats, and amounts sometimes include currency symbols. The model learns patterns from noise rather than signal.
Common quality failures and what they do to a model:
Data issue | Effect on the model |
Incorrect joins | Mislabeled training segments |
Inconsistent date formats | Broken time-series predictions |
Careless handling of missing values | Systematic bias |
Duplicate records | Overweighted patterns and inflated accuracy |
Unrepresentative samples | Poor performance on real-world groups |
The business cost is significant. Gartner ties AI project abandonment directly to a lack of AI-ready data. No neural network architecture overcomes training data full of errors. Clean data for machine learning isn't a technical checkbox. It decides whether AI investments return value or drain budgets.
Industry leaders have shifted their focus accordingly. Andrew Ng, founder of Google Brain and DeepLearning.AI, calls this approach data-centric AI: "systematically engineering the data used to build an AI system." In one steel-sheet inspection project, two months of model tuning left accuracy at 76.2%. Two weeks of data-centric work raised it to 93.1%.
Turn Data Quality from Cost Center to Competitive Advantage
Eliminate the millions of dollars incurred annually due to poor data quality. See how automated profiling and validation ensure every dataset meets AI-ready standards before training begins.

What are The 5 Steps of AI Data Preparation?
The five steps of AI data preparation are ingestion, cleaning, transformation, feature creation, and validation. Each one removes a different kind of risk before the data reaches a model.
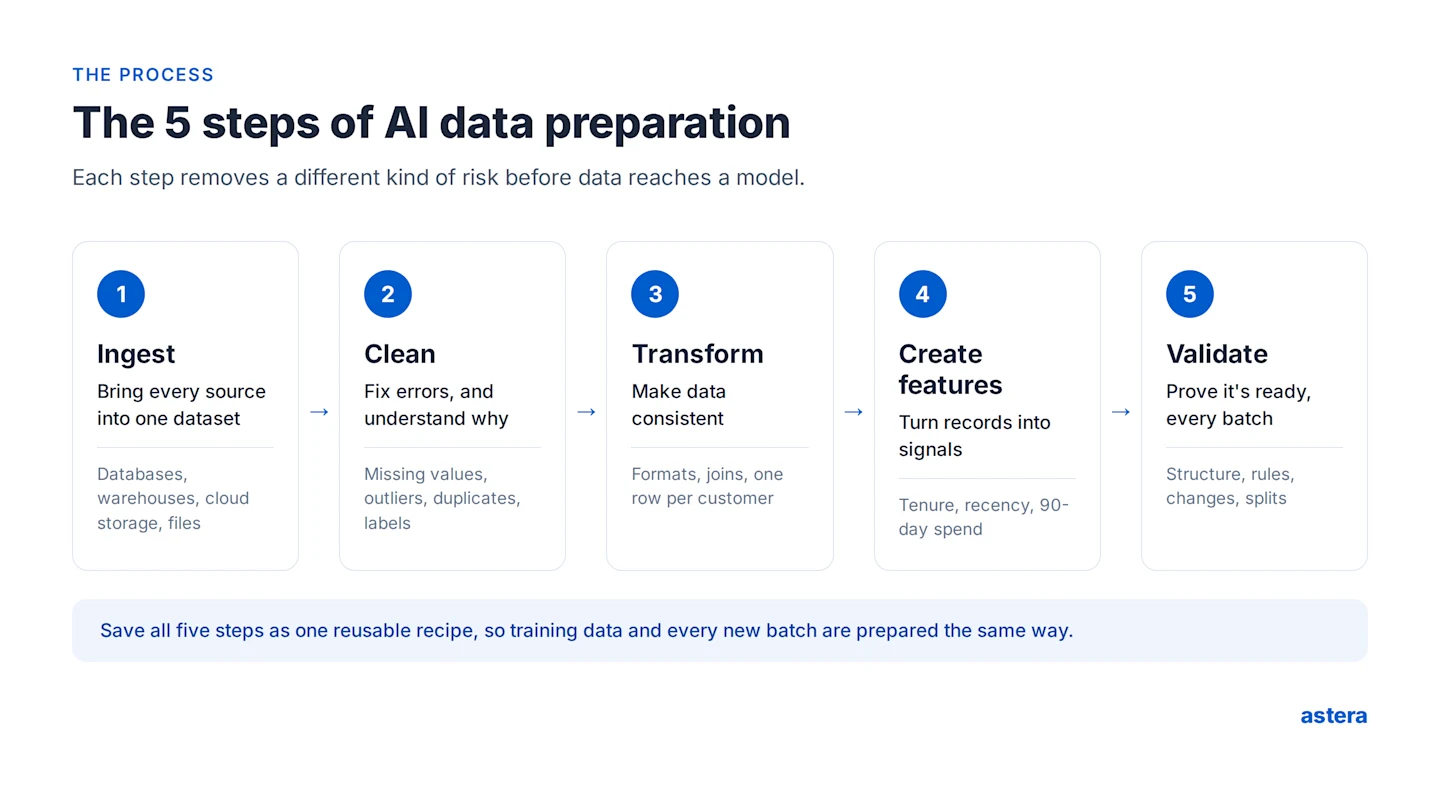
1. Data ingestion: bring every source together
Data ingestion pulls data from databases, cloud storage, data warehouses, SaaS exports, and spreadsheets into one working dataset. A churn model, for example, might need contract data from the CRM, invoices from billing, and ticket history from the help desk.
Three habits make ingestion AI-ready:
Keep an untouched copy of the raw data. Databricks' medallion architecture formalizes this: raw data lands as-is, and cleaned versions are built from it. If your cleaning rules change, you can rebuild the training set instead of starting over.
Keep the dates. Record when each event happened, not just the current value of each field. You will need this in step 4 and when avoiding the pitfalls below.
Load changes, not everything. Incremental loads pick up only new and changed records, so datasets stay current without reprocessing history.
In Astera Dataprep:
Connect to PostgreSQL, MySQL, SQL Server, Oracle, Snowflake, Redshift, BigQuery, Amazon S3, Azure, Google Cloud, and files such as CSV, Excel, JSON, XML, and Parquet. Change data capture handles incremental updates automatically.
2. Data cleaning: fix what's wrong, and understand why
Data cleaning is more than deleting bad rows. The right fix depends on why the data is wrong.
Missing values: Ask why a value is missing before you fill it. A blank "cancellation reason" on an active account is expected. A blank on a cancelled account is a data problem. Sometimes the blank itself is a signal: customers who never fill in a profile field may behave differently. In that case, keep a "was missing" flag alongside the filled value.
Outliers: Separate errors from rare but real events. A customer aged 212 is a typo. A single $2 million order may be your most important customer, and exactly the kind of case a model needs to learn from.
Duplicates: "Jon Smith, 12 Main St" and "John Smith, 12 Main Street" are one customer. Duplicates make a model over-learn the patterns of whoever appears most often.
Labels: Check the column you want to predict with the same care. If some churned customers are recorded as active, the model learns the wrong lesson.
In Astera Dataprep:
Built-in profiling detects nulls, duplicates, and invalid formats automatically, so you see problems before you fix them. Then describe the fix in plain language, for example "Remove duplicate customers based on email" or "Fill missing region values with Unknown," and check the result in the live preview grid.
3. Data transformation: make the data consistent and model-ready
Transformation reshapes data into the consistent, structured form models expect. Learn more in our guide to data preprocessing.
Standardize formats: one date format, one currency, one unit, one spelling per category.
Reshape tables: models expect one row per thing you are predicting (one row per customer, per order, or per machine). That often means joining, pivoting, or aggregating tables.
Handle categories carefully: group rare categories into "Other" so a model doesn't treat a value that appears three times as meaningful.
Keep units comparable: revenue in dollars and tenure in months sit on very different scales. Data scientists may rescale them later, but consistent, well-documented units make that step reliable.
In Astera Dataprep:
Choose from more than 50 transformations, including split, merge, pivot, unpivot, and derived columns. Or ask in chat, for example "Standardize all dates to YYYY-MM-DD" or "Join invoices with customers on customer ID." The AI keeps track of your schema and previous steps, so follow-up instructions build on what you have already done.
4. Feature creation: turn records into signals
Feature creation, also called feature engineering, turns raw fields into measures that capture behavior. This is where business knowledge matters most, and where business users often know more than the data scientists.
Raw data | Features a model can use |
Order dates and amounts | Orders in the last 30 and 90 days, average order value, days since last order |
Support tickets | Tickets per month, share of tickets escalated, days since last complaint |
Contract start and end dates | Tenure in months, days until renewal |
Monthly usage | Change in usage over the last quarter |
One rule matters above all: every feature must use only information that was available at the moment of the prediction. Feature platforms such as Feast enforce this with "point-in-time" joins that look up each value as it stood on the date in question. If you build features by hand, apply the same discipline.
In Astera Dataprep:
Ask for a metric by name, such as "Profit" or "Growth Rate," and Dataprep infers the right formula. Every feature is saved as a step in your recipe, so the same logic runs the same way every time.
5. Validation: prove the data is ready
Validation checks that the prepared dataset is correct before a model depends on it, and it keeps checking as new data arrives. Google's research team, which validates petabytes of production data every day, warns that "errors in the input data can nullify any benefits on speed and accuracy for training and inference."
A good validation pass answers four questions:
Is the structure right? Expected columns, data types, and allowed values are all present.
Does it follow business rules? A ship date never comes before an order date, and a discount never exceeds 100%.
Does it look like last time? Compare each new batch with the previous one. A sudden jump in blanks, or a category share that doubles overnight, usually means a source system changed.
Is it split correctly? Data used to test a model must be kept separate from data used to train it, and for forecasts the test data should come from a later period.
In Astera Dataprep:
Saved recipes apply the same fixes and checks to every new batch, and monitoring tracks success rates, runtimes, and failures. Alerts notify you when a pipeline fails or needs attention, before a bad batch reaches the model.
For a data science view of these steps, read the importance of data preparation for machine learning.
Automate All Five Steps in One Platform
Stop writing custom scripts for every transformation. Use natural language to ingest, clean, transform, engineer, and validate—all in a unified workspace with instant preview.
Three Pitfalls That Quietly Break AI Models
The most expensive data problems don't cause errors. The model trains, the test scores look good, and it fails only after it goes live. Watch for these three.
1. Training data that "knows the future"
Data scientists call this data leakage: the training data includes information the model won't have when it makes real predictions. Because the model can "see the answer," test scores look excellent, then collapse in production.
Common examples in business data:
A churn dataset includes a "cancellation date" or "retention offer sent" field. Those only exist because the customer churned.
A feature such as "total spend" is calculated over all time, including months after the date being predicted.
Duplicate customers end up in both the training data and the test data, so the model is tested on records it has already seen.
The fix is discipline, not technology. For every column, ask: "Would we know this value at the moment we make the prediction?" If not, remove it or recalculate it as of that date. Split training and test data before you calculate averages, fill-in values, or any other statistics from the data. The scikit-learn guide that data scientists rely on puts it simply: learn every transformation "only from the training data."
2. Training data that doesn't match live data
A model is trained on data prepared one way, then fed live data prepared another way, often by a different team with different code. Google calls this training-serving skew. Its Rules of Machine Learning advise teams to "re-use code between your training pipeline and your serving pipeline whenever possible" (Rule #32). When YouTube's home page began logging the exact features used at serving time and training on them, Google reported "significant quality improvements and a reduction in code complexity."
For business teams, the lesson is simple: define each preparation step once and run the same definition everywhere. A recipe that prepares the training data should also prepare every new batch the model scores.
3. Data that is biased or poorly governed
If the training data under-represents a region, product line, or customer group, the model will perform worst for exactly those groups. Check that every segment the model will serve appears in the data in meaningful numbers, and document any gaps you can't close.
Governance matters just as much. Mask personal data that the model doesn't need, keep access rules in place, and record where each dataset came from and how it was changed. Regulation is making this mandatory: for high-risk AI systems, Article 10 of the EU AI Act requires training, validation, and testing data to be "relevant, sufficiently representative, and to the best extent possible, free of errors and complete." It also requires documented governance of preparation steps such as "annotation, labelling, cleaning."
Preparing Data for AI Assistants and Copilots
AI data preparation isn't only for predictive models. When teams connect copilots and AI assistants to company data, the quality of their answers depends on the same work. Microsoft's guidance on preparing data for Copilot warns that when data is "unstructured or ambiguous," AI outputs "might be generic, inaccurate, or even misleading."
For structured data, such as tables, reports, and semantic models, focus on four things:
Clear names. Rename cryptic columns such as cst_rev_q to "Customer revenue (quarter)." An assistant can only map a question to a column it understands.
One definition per metric. If "active customer" means different things in two tables, the assistant will give different answers to the same question. Standardize the definition once.
No duplicates or stale records. Duplicated customers inflate totals. Outdated records produce confident but wrong answers.
Only the fields it needs. Remove or mask sensitive columns before an assistant can reach them.
For documents such as PDFs, contracts, and policies, preparation also includes extracting text and tables, splitting documents into sections, and tagging each section with its source and date. Anthropic's Contextual Retrieval research shows how much this matters: adding a short description of where each section sits in its document cut failed searches by 35%, and by 67% when combined with keyword search and reranking. To pull structured data out of documents first, Astera ReportMiner automates extraction from PDFs and scanned files.
Why Manual Data Preparation Breaks Down
Most teams start with spreadsheets and scripts. That works for a first prototype, then runs into the same limits:
It can't be repeated reliably. A spreadsheet cleanup done by hand has to be redone, slightly differently, every time new data arrives. That is exactly how training data and live data drift apart.
It depends on a few people. When preparation lives in one engineer's scripts, every change waits in their queue, and the people who understand the business can't check the logic.
Errors are invisible. A formula dragged one row too far or a join on the wrong key rarely causes an error message. It just produces a slightly wrong dataset.
It doesn't scale. What works on 10,000 rows in Excel fails on millions of rows from a warehouse.
The result is that AI projects that should take weeks stretch into months.
Spreadsheets vs. Scripts vs. ETL vs. AI-Powered Data Prep
Spreadsheets | SQL or Python scripts | Traditional ETL tools | AI-powered data prep (Astera Dataprep) | |
Who can do the work | Business users | Engineers and data scientists | Data engineers | Business users and data teams |
How you build it | Manual edits and formulas | Code | Visual mappings configured by specialists | Plain-language chat plus 50+ built-in transformations |
Repeatable | No | Yes, if maintained | Yes | Yes, through saved recipes |
Handles large data | Limited | Yes | Yes | Yes, scales to millions of rows |
Finds quality issues | Manual inspection | Custom checks you write | Rule-based checks you configure | Automatic profiling of nulls, duplicates, and invalid formats |
Keeps data fresh | Manual refresh | Custom scheduling | Scheduled jobs | Scheduling, incremental loads, monitoring, and alerts |
Stop Wrestling with Data. Start Building Models.
See how conversational data prep eliminates the bottlenecks slowing your AI initiatives. Transform weeks of manual work into minutes of natural language commands.
Case Example: Astera Dataprep's Approach to AI Data Preparation
Astera Dataprep exemplifies the new generation of natural language data preparation tools designed specifically for the AI era. At its core sits a conversational interface that eliminates the technical barrier previously keeping domain experts from directly participating in data preparation.
Conversational data preparation means describing tasks in everyday language. "Clean missing values in the price column." "Join sales data with customer information on customer ID." "Standardize all dates to YYYY-MM-DD format." The platform interprets instructions and executes appropriate transformations. Domain experts who best understand quality requirements can now directly participate without coding.
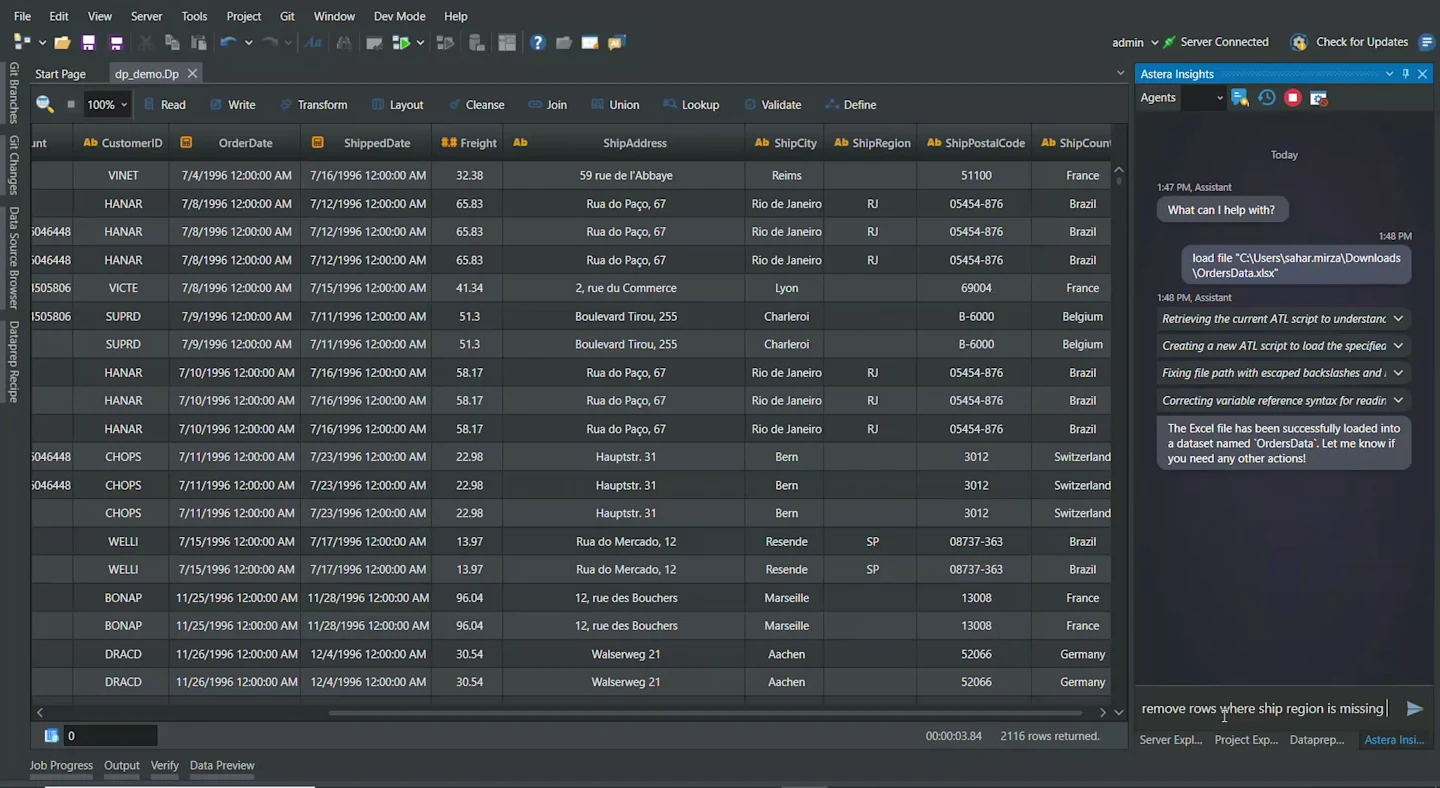
Conversational AI data preparation in Astera Dataprep
Built-in profiling automatically highlights errors, anomalies, duplicate entries, and missing data across datasets. Rather than writing queries to discover quality issues, users get immediate visibility into data health. The system flags problematic records, suggests corrections, and allows conversational fixes.
Real-time preview reflects every transformation immediately in an Excel-like grid, providing instant feedback. Users see the impact of each change before committing it, reducing trial-and-error cycles typical of script-based approaches. Visual confirmation builds confidence and accelerates preparation.
Reusable recipes capture data preparation logic as step-by-step instructions applicable to new datasets with similar structures. Build a customer data cleansing recipe once, then apply it automatically every time new customer records arrive. This ensures consistency and eliminates redundant work.
Comprehensive connectivity works with structured and semi-structured data from files (Excel, CSV, delimited formats), databases (SQL Server, PostgreSQL, MySQL, Oracle), cloud sources (AWS, Azure, Google Cloud), and API endpoints. Unified connectivity solves the fragmentation problem plaguing traditional approaches.
Scheduled workflows run automatically, ensuring ML pipelines always receive fresh, properly prepared data. Data preparation transforms from manual bottleneck into reliable, automated process operating continuously without human intervention.
Security architecture keeps data within the user's environment—never sending it to external large language models. The platform uses LLMs solely to interpret natural language instructions and invoke built-in transformations. This addresses legitimate security concerns about exposing sensitive data to external AI services.
What previously required data engineers writing SQL scripts for several days now becomes conversational commands executed in minutes. Complex multi-step transformations that demanded specialized Python skills now get built through intuitive prompts. Teams struggling with quality backlogs can now maintain consistent standards through automated profiling and reusable recipes.
Astera Dataprep empowers technical and non-technical teams to prepare AI-ready datasets faster—ensuring quality, consistency, and auditability before models being training.
See How Astera Dataprep Transforms Your Workflow
We know every organization has unique data preparation challenges. Discuss your specific requirements with us to see customized demonstrations of features that solve your bottlenecks.
AI Data Preparation for the Future
AI results are decided long before a model is trained. Clean, consistent, well-governed data decides whether a fraud model catches criminals or blocks loyal customers, and whether a copilot gives the right number or a confident guess.
For years, that work sat with a few engineers and a lot of scripts. It is moving to the people who understand the data best, supported by tools that make every step visible, repeatable, and automated. Teams that make that shift spend less time fixing data and more time using it.